Key Statistics
Key Takeaways
- Standard Burn-in is the largest testing type in the report scope because it remains the baseline method for screening early-life failures across production devices, while accelerated and programmable-load approaches add value where thermal density and workload behavior are more demanding.
- Data-Center Accelerators are the leading application, reflecting the economic cost of failures in high-value GPU and accelerator fleets, the power density of AI hardware and the need to validate complete packaged devices before deployment into service-level-agreement-driven infrastructure.
- North America is treated as the largest 2025 market because the report page states that the United States currently dominates, while Asia Pacific is identified as the region poised to become the largest and fastest-growing as advanced packaging and semiconductor manufacturing scale.
- Advanced packaging is reshaping burn-in requirements; chiplets, HBM, large packages and liquid-cooled AI systems raise the cost of latent defects and increase the importance of test access, thermal control and system-level reliability screening.
- The supplier landscape includes different roles: Advantest and other test-equipment specialists supply platforms, OSAT/foundry participants provide packaging and test services, while chip companies such as NVIDIA, AMD, Qualcomm and Broadcom are major users or design stakeholders rather than directly equivalent burn-in equipment vendors.
AI Chip Burn-in Test Market Overview
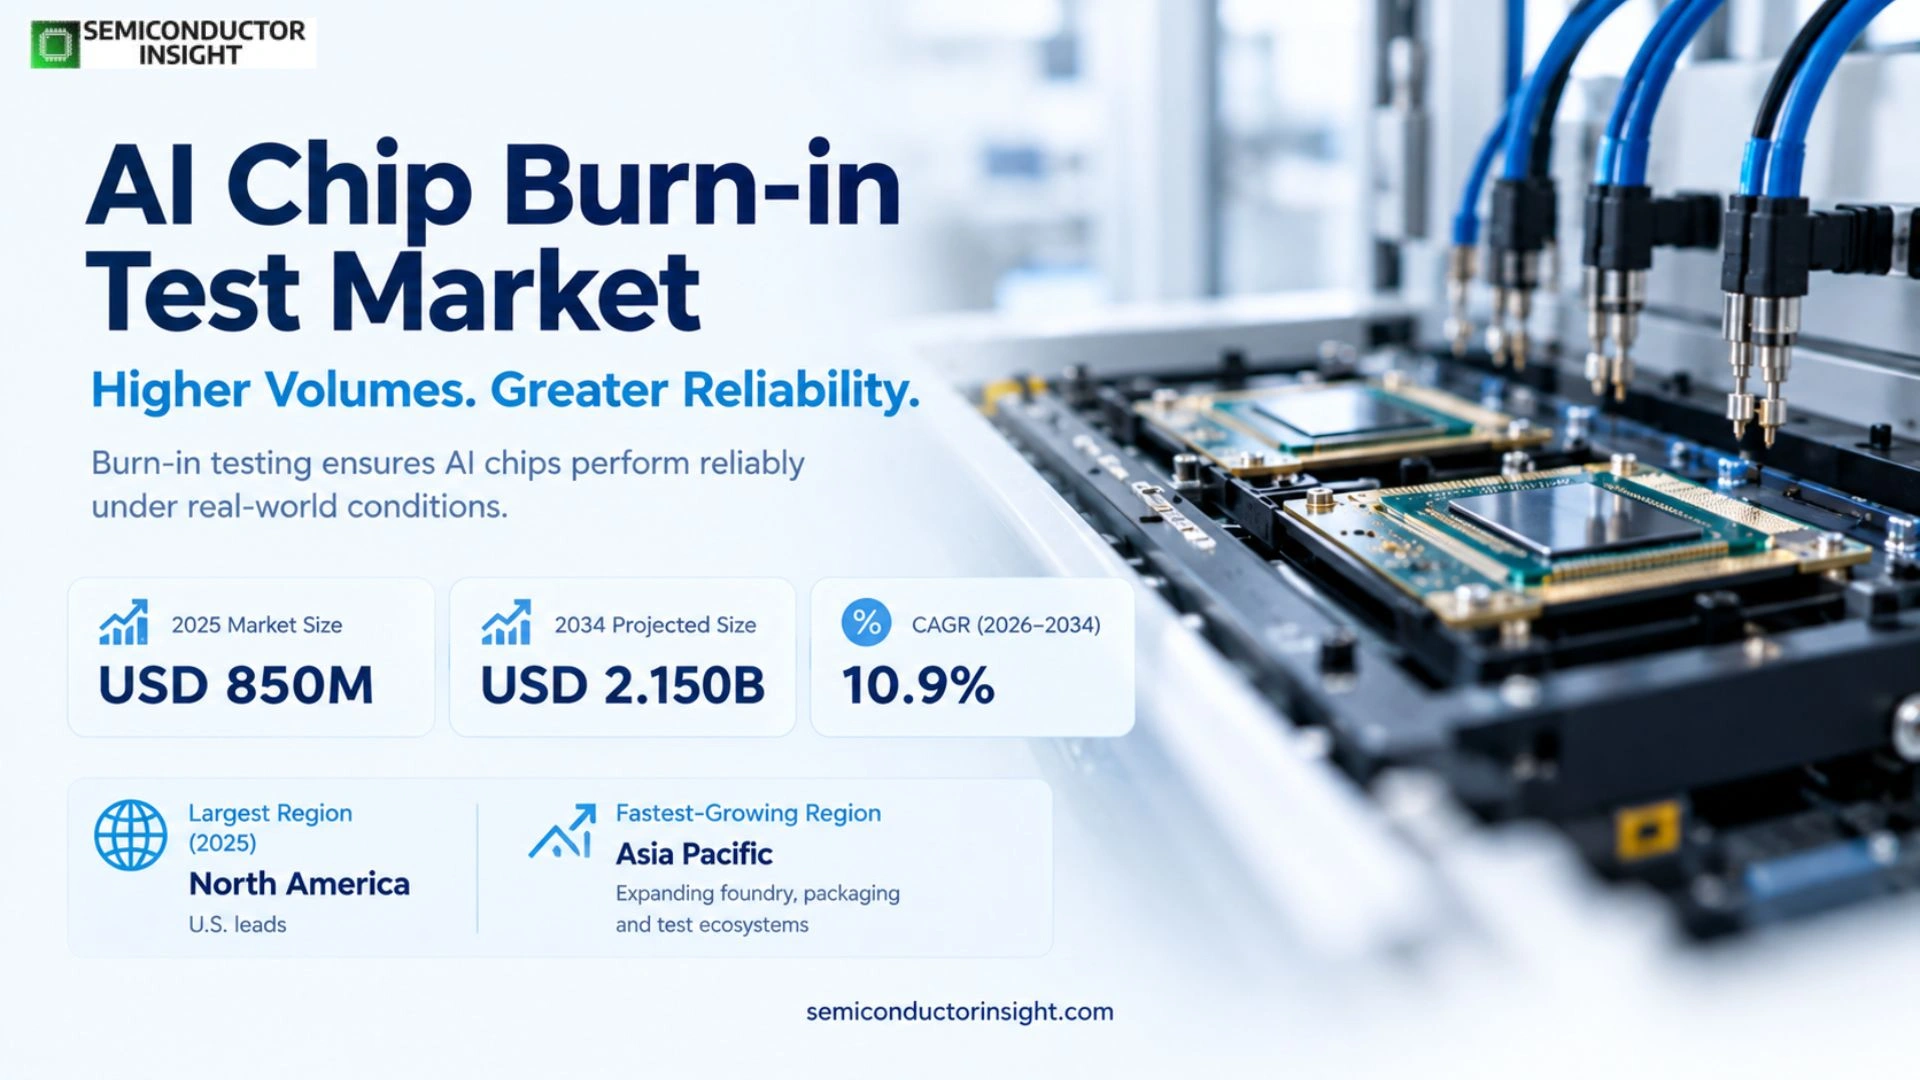
AI Chip Burn-in Test Market was valued at USD 850 million in 2025 and is projected to reach USD 2.150 billion by 2034. The two published market-size anchors imply a 10.9% CAGR for 2026–2034. North America is treated as the largest market in 2025 because the report page explicitly states that the United States currently dominates, while Asia Pacific is positioned as the fastest-growing region as leading foundry, packaging and test ecosystems expand AI-related capacity.
AI chip burn-in testing subjects accelerators, processors and other high-performance devices to controlled electrical and thermal stress for an extended period so that early-life defects can be exposed before field deployment. The commercial problem is unusually important for AI hardware because individual devices can be expensive, they are installed in dense clusters, and failures can disrupt systems that must meet demanding uptime targets. Burn-in therefore sits between semiconductor manufacturing, advanced packaging, reliability engineering and system deployment rather than functioning as a generic end-of-line test.
The technical challenge is increasing as AI hardware moves toward larger packages, chiplets, high-bandwidth memory and higher power density. A package can contain multiple valuable die and memory stacks, so discovering a latent defect after final integration destroys more value than rejecting a low-cost single die earlier in the process. This changes test economics: suppliers need higher parallelism, better thermal management, more flexible stimulus and data analytics capable of isolating failure mechanisms without extending cycle time so far that test becomes a capacity bottleneck.
External industry evidence supports the direction of demand. Teradyne’s 2025 annual filing reported an 18.8% increase in semiconductor-test revenue and stated that AI-related demand represented the majority of its semiconductor-test revenue in the second half of 2025. That company result is not the market size for AI burn-in, but it demonstrates how quickly AI-related semiconductor test demand is influencing major equipment suppliers. It also shows why test platforms are being designed around higher current, advanced packaging and more complex system-level validation.
Advanced packaging is another structural driver. TSMC positions CoWoS as a platform for high-performance computing and AI, while the U.S. Department of Commerce finalized up to USD 407 million in CHIPS incentives for Amkor’s advanced packaging and test facility in Arizona in December 2024. As more AI devices use complex package integration, burn-in must be coordinated with package design, cooling and downstream system test. The market implication is tighter coupling among chip designers, foundries, OSATs and test-equipment vendors.
Segment Analysis: By Type
By type, the report page segments the market into Standard Burn-in, Accelerated Stress Burn-in and Programmable Load Burn-in. Standard burn-in remains the baseline screening approach, while accelerated stress techniques increase stress severity to expose weaknesses faster and programmable-load systems are increasingly important for AI devices whose real operating behavior is highly dynamic. The correct method depends on device value, expected field life, package thermal behavior and the cost of test time.
| Type | Technical / purchasing role | Market position |
|---|---|---|
| Standard Burn-in | Standard burn-in applies defined voltage, temperature and operating conditions for a set duration to screen early-life failures before shipment. It is widely used because qualification methods, fixtures and reliability models are well understood. For AI hardware, the method remains relevant for production screening, but conventional static conditions may not fully reproduce the highly variable power and thermal behavior of modern accelerators operating under bursty inference or training workloads. | Largest type. Standard burn-in provides the broadest installed base and is the default reliability screen where cost, throughput and established methodology matter. Its commercial advantage is maturity, but equipment suppliers must keep increasing current delivery, channel density and thermal-control capability as device power rises. The segment therefore evolves through platform upgrades rather than being displaced by a completely different test philosophy. |
| Accelerated Stress Burn-in | Accelerated stress burn-in raises thermal, electrical or workload stress so that latent defects emerge in less elapsed time. The method can reduce screening duration if the acceleration model remains valid, but excessive stress may create failures that would not occur under normal field use. Engineers therefore need careful correlation between stress conditions and the actual reliability mechanisms of advanced packages, especially when chiplets and HBM introduce multiple materials and thermal interfaces. | A high-value segment for mission-critical and high-cost devices where shorter detection time or higher confidence can justify more sophisticated equipment. Adoption grows as device value and package complexity rise, but commercial expansion depends on proving that the stress recipe improves screening without causing overkill. This favors suppliers with precise thermal control, instrumentation and analytics rather than simple high-temperature chambers. |
| Programmable Load Burn-in | Programmable load burn-in applies controlled, time-varying electrical workloads that better mimic AI accelerator behavior than a fixed static load. The approach can exercise power-management paths, memory interfaces and compute blocks under realistic transitions, creating a richer reliability signature. Implementing it requires high-current power delivery, synchronized control and data capture across many devices, so test-system architecture becomes materially more complex. | An expanding technology direction as AI chips become more workload-sensitive. The value proposition is strongest for data-center accelerators and other high-performance devices where dynamic power behavior is part of the failure risk. Equipment vendors can differentiate through scalable power delivery, software-defined profiles and analytics, but customers will only pay for complexity that improves correlation to field failures or reduces escape rates. |
Secondary segmentation: end user, reliability requirement and deployment scale
The report further segments demand by end user into Cloud Service Providers, OEMs for Autonomous Vehicles and Industrial Automation Firms; by reliability requirement into Mission-Critical, High-Performance and Cost-Sensitive; and by deployment scale into Large-Scale Data-Centers, Mid-Size Edge Installations and Embedded IoT Devices. These axes materially change test economics. A mission-critical accelerator deployed by the thousands can justify longer, richer screening because a field failure has high operational cost, while cost-sensitive embedded devices require tighter screening time and parallelism. Test-platform suppliers therefore compete on a throughput-versus-coverage frontier rather than offering one burn-in recipe to every customer.
Segment Analysis: By Application
By application, the report page lists Data-Center Accelerators, Edge Inference Devices, Autonomous System Controllers and Others. Data-center accelerators are the leading application because AI infrastructure combines high device value, high power density and stringent uptime expectations. Autonomous controllers carry a different reliability logic centered on safety and long field life, while edge devices put more pressure on test cost because unit economics can be tighter.
| Application | Demand characteristics |
|---|---|
| Data-Center Accelerators | Data-center GPUs, AI ASICs and related accelerators operate in dense servers where one failed device can trigger maintenance, reduce cluster availability or violate service commitments. High package value and power density make burn-in economically rational, particularly when the device integrates HBM and advanced packaging. Test programs emphasize high current, controlled cooling, parallelism and correlation to real workloads. The purchasing trigger is the cost of field failure relative to screening time, not merely a generic quality target. |
| Edge Inference Devices | Edge inference devices range from industrial gateways to network and vision systems, creating a wide spread of volumes, power levels and field environments. Burn-in is most valuable where devices face temperature variation, long unattended service or costly maintenance. Suppliers must balance coverage with unit economics because edge products can be more price sensitive than data-center accelerators. Flexible test platforms that can reuse hardware across device families therefore have a commercial advantage. |
| Autonomous System Controllers | Autonomous vehicle and machine controllers require reliability across long service lives, wide temperature ranges and safety-critical operating conditions. Burn-in contributes to early-failure screening but is only one element of a broader qualification and functional-safety process. The commercial opportunity is high-value because customers may demand traceability, deterministic screening and long-term support. Test suppliers need close engineering engagement to map stress profiles to actual failure mechanisms rather than applying a generic data-center recipe. |
| Others | Other applications include specialized AI processors for communications, industrial automation, medical systems and embedded devices. The common requirement is to detect latent reliability problems before deployment, but acceptable test cost varies sharply. Suppliers need modular architectures that can scale channel count, power and thermal control to the device value. This heterogeneous segment favors reusable software and configurable fixtures, because dedicated test hardware for every low-volume AI device would be economically inefficient. |
Regional Analysis
North America is the largest AI chip burn-in test market in 2025, based on the report page’s statement that the United States currently dominates. Asia Pacific is the fastest-growing region and is positioned to become the largest as Taiwan, South Korea, Japan and China expand foundry, advanced-packaging and semiconductor-test activity. Europe is driven by automotive and industrial reliability, while South America and Middle East & Africa remain smaller markets centered on imported AI hardware, data centers and localized engineering services.
How does regional AI burn-in demand follow the semiconductor value chain?
Burn-in demand appears where valuable AI devices are designed, packaged, tested or deployed at scale. North America concentrates AI chip design, hyperscale computing and a growing domestic advanced-packaging push; Asia Pacific concentrates foundry, OSAT and electronics manufacturing; Europe brings automotive and industrial reliability requirements; and emerging regions primarily consume finished systems rather than host the same depth of semiconductor test infrastructure. This makes regional market growth closely linked to where advanced packaging and high-volume AI deployment capacity is being added.
| Region | Position | Growth outlook | Demand profile | What decides supplier selection |
|---|---|---|---|---|
| North America | Largest in 2025 | High | AI design + hyperscale + domestic packaging/test | High-power capability, analytics, local support and qualification depth |
| Asia Pacific | Fastest-growing | Highest | Foundry + OSAT + advanced packaging | Throughput, local engineering, package support and cost |
| Europe | Significant | Steady | Automotive + industrial reliability | Safety, traceability, energy efficiency and long lifecycle support |
| South America | Nascent | Emerging | Imported AI systems + localized services | Cost, distributor support and access to advanced equipment |
| Middle East & Africa | Emerging | Selective high growth | AI data centers + sovereign digital investment | Service availability, infrastructure and imported equipment support |
AI Chip Burn-in Test Market Competitive Landscape
The report’s company list mixes several roles across the ecosystem: chip designers and IDM/foundry companies, outsourced assembly and test providers, and specialized test-equipment vendors. For competitive analysis, those roles must be separated. Advantest is a direct test-platform supplier; ASE and foundry/packaging providers can deliver test services; NVIDIA, AMD, Qualcomm, Broadcom and similar chip companies are major design stakeholders and demand creators rather than direct equivalents to a burn-in system manufacturer. Competition therefore occurs across equipment, service and co-engineering layers.
Test-equipment suppliers compete on electrical density, thermal control, parallelism, instrumentation accuracy, software and analytics. Advantest’s 2025 disclosures around the 7038 platform and broader AI/HPC test portfolio show the direction: high-power devices require equipment that can support advanced cooling and large-scale system-level or burn-in workflows. The commercial moat is not only hardware throughput; it is installed engineering knowledge, device-interface design and the software used to correlate failures across production lots.
OSAT and advanced-packaging suppliers compete through process integration. As chiplets and HBM move more value into one package, customers want reliability screening closer to assembly and package test so defective combinations are identified before system deployment. ASE and similar service providers can capture value by combining packaging, final test and reliability services. The equipment supplier remains important, but the buying decision may be made jointly by the chip company and the packaging/test partner rather than by the end system operator.
Chip designers and cloud customers shape test requirements even when they do not sell burn-in equipment. NVIDIA, AMD, Intel, Qualcomm, Marvell, Broadcom and others define power, package and workload behavior, while hyperscale operators set uptime and fleet-maintenance expectations. This creates a co-engineering market in which equipment vendors must support roadmaps before volume ramps. Winning a high-volume AI platform can drive demand for testers, handlers, sockets, cooling and software across multiple manufacturing sites.
| Competitive tier | Companies / participants | How competition works |
|---|---|---|
| Test equipment and reliability platforms | Advantest and other semiconductor-test specialists | Direct equipment suppliers compete on high-current delivery, channel density, thermal control, liquid-cooling compatibility, test software and analytics. AI devices stress all of these simultaneously. The strongest competitive positions come from platforms that can be upgraded across several device generations and from field engineering teams that help customers correlate burn-in results to wafer, package and system failures without sacrificing too much production throughput. |
| Packaging and outsourced test services | ASE; foundry/OSAT advanced-test operations; Amkor in the wider ecosystem | Service providers capture value by integrating burn-in and final reliability screening with advanced packaging. The more expensive the assembled package, the greater the incentive to find defects before shipment. Customers value traceability, throughput and the ability to coordinate package, thermal and electrical test data. Geographic capacity expansion can also move demand for equipment because each new advanced-packaging site requires its own reliability and test infrastructure. |
| AI chip designers / IDMs / platform companies | NVIDIA; Intel/Habana; TSMC; Qualcomm; Samsung; AMD; GlobalFoundries; Marvell; Broadcom; Texas Instruments; Lattice | These profiled companies influence burn-in through device architecture, package design, reliability requirements and production volume, but they do not all compete as direct burn-in equipment sellers. Their roadmaps determine required power, temperature, workload and test access. Equipment suppliers and OSATs that are engaged early can design scalable interfaces before volume ramp, creating a relationship that may persist across multiple chip generations. |
Key participants profiled
The report page profiles NVIDIA Corporation; Intel Corporation through Habana Labs; TSMC; Advanced Semiconductor Engineering; Advantest Corporation; Qualcomm Technologies; Samsung Electronics; AMD; GlobalFoundries; Marvell; Broadcom; Texas Instruments; and Lattice Semiconductor. The list is valuable as an ecosystem map, but commercial roles differ. Advantest directly supplies semiconductor test systems, ASE provides packaging and test services, TSMC and GlobalFoundries are manufacturing participants, and many others are AI or semiconductor device companies whose products create the reliability-screening requirement.
AI Chip Burn-in Test Market Production Capacity Analysis
Burn-in capacity is constrained by more than the number of chambers or testers. AI devices require high-current power delivery, device-interface boards or sockets, thermal management, cooling infrastructure, data acquisition and engineering recipes that correlate stress results to real failure mechanisms. As advanced packaging increases device value and power density, test-floor capacity can become a meaningful production constraint. New packaging and test investments in North America and Asia Pacific therefore create demand for both equipment and skilled reliability engineering.
The U.S. Department of Commerce announced a finalized CHIPS award of up to USD 407 million to Amkor in December 2024 for an advanced packaging and test facility in Arizona. The award is broader than AI burn-in, but it is relevant because domestic advanced packaging creates a local need for final test, reliability infrastructure and high-value package screening. As advanced AI packages are produced closer to U.S. design and data-center customers, test-equipment vendors gain an additional regional capacity node that requires engineering support and installed tools.
Asia Pacific remains the manufacturing center of gravity for advanced semiconductor packaging and test. TSMC’s CoWoS platform is explicitly positioned for HPC and AI products, and the region also contains major OSAT, memory and semiconductor manufacturing capacity. The test implication is direct: more packaged AI devices and HBM integration generate more demand for burn-in, final test and thermal characterization. Equipment vendors must therefore scale support close to Taiwan, South Korea, Japan, China and Southeast Asian production sites.
| Capacity layer | Key locations / participants | Constraint and market implication |
|---|---|---|
| Tester and power-delivery capacity | Advantest and semiconductor-test equipment suppliers | AI accelerators can require very high current and multiple power rails, so conventional low-power burn-in architectures may not scale economically. Capacity depends on how many devices can be stressed in parallel without compromising measurement or electrical stability. Equipment suppliers gain value when they increase channel density and power while preserving accuracy, because customers can raise throughput without expanding floor space proportionally. |
| Thermal and cooling infrastructure | Burn-in racks, liquid-cooling systems, thermal interfaces and facility utilities | High-power AI devices create large heat loads during stress. Air cooling may be insufficient at the highest power densities, pushing burn-in toward liquid-cooled or otherwise enhanced thermal systems. Advantest’s 2025 communications around the 7038 platform highlight liquid-cooling support for system-level and burn-in environments. Facility chilled-water capacity, heat rejection and thermal fixture design therefore become practical limits on how quickly a test floor can scale. |
| Device interfaces and sockets | Socket, load-board and interface suppliers co-engineered with chip/package teams | Advanced packages have dense I/O, high current and tight mechanical tolerances. The interface must survive repeated thermal cycles while maintaining electrical integrity. A socket or load-board bottleneck can delay an otherwise available tester, and redesign may be required for each package generation. This creates recurring engineering revenue and favors suppliers that engage early with device roadmaps rather than treating burn-in hardware as a generic commodity. |
| Reliability engineering and analytics | Chip companies, foundries, OSATs and test-platform software teams | Physical equipment only creates value when stress recipes identify relevant failures without excessive overkill. Engineers need correlation across wafer test, package assembly, burn-in, final test and field returns. AI-assisted analytics can shorten root-cause work and identify drift across lots, but models require consistent data. Skilled reliability engineering is therefore a capacity constraint in its own right, especially during new package ramps where failure mechanisms are not yet mature. |
AI Chip Burn-in Test Market Market Dynamics: Drivers, Restraints and Opportunities
Demand is accelerating because AI accelerators are becoming more valuable, power dense and package complex at the same time that cloud and autonomous-system customers expect high uptime. The main restraints are long test time, high capital and energy cost, thermal complexity and the risk of over-screening. The strongest opportunities lie in high-parallelism liquid-cooled platforms, programmable workload stress, integrated package/test analytics and regional advanced-packaging capacity expansion.
MARKET DRIVERS
What is accelerating demand?
| Driver | Directional impact* | Commercial mechanism |
|---|---|---|
| Higher AI accelerator value and fleet uptime requirements | High | The cost of a field failure rises with device value, cluster density and service commitments, increasing willingness to pay for stronger reliability screening. |
| Advanced packaging and HBM integration | High | More die and memory are combined into one package, so latent defects destroy more value and require tighter thermal/electrical screening. |
| Rapid growth of AI-related semiconductor test demand | High | Major test-equipment suppliers report strong AI-related demand, driving new high-power platforms and engineering investment. |
| Domestic packaging/test capacity expansion | Medium–High | New facilities in North America and continued Asian investment create additional installed bases for burn-in equipment and services. |
The economics of field failure are worsening
AI accelerators are expensive devices deployed in dense servers and clusters. A failure can remove compute capacity, trigger maintenance and disrupt workloads with contractual uptime expectations. That makes screening economics different from a low-cost consumer IC: spending more test time is rational when the cost of an escaped defect is much higher. Cloud operators and chip suppliers therefore push reliability requirements upstream, increasing demand for burn-in platforms that can stress devices at realistic power while maintaining production throughput.
Advanced packaging increases value at risk before shipment
Chiplet and HBM architectures place several high-value elements into one advanced package. If a latent defect is discovered after integration or field deployment, the economic loss includes more than one die. TSMC’s CoWoS positioning for AI and HPC illustrates the scale of this packaging transition. The supplier response is more integrated reliability screening at package level, stronger thermal characterization and greater interest in identifying weak devices before they consume downstream system-assembly and deployment resources.
AI test is becoming a measurable growth driver for equipment suppliers
Teradyne reported that semiconductor-test revenue increased 18.8% in 2025 and that AI-related demand made up the majority of its semiconductor-test revenue in the second half of the year. Those company figures are not the burn-in market size, but they provide direct evidence that AI is changing semiconductor-test demand. Equipment vendors are therefore allocating engineering to high-power, advanced-packaging and data-analytics capabilities, accelerating the technology available to burn-in users.
New packaging and test capacity creates fresh equipment demand
The United States is investing in domestic advanced packaging while Asia Pacific continues to expand leading foundry and OSAT ecosystems. The U.S. Commerce award of up to USD 407 million to Amkor for an Arizona advanced packaging and test facility is one example of new regional capacity. Each greenfield or expanded site needs reliability infrastructure, sockets, cooling, software and trained engineers, so manufacturing policy can translate into burn-in demand even when the policy is not specific to one test step.
MARKET RESTRAINTS
What can slow market conversion?
| Restraint | Directional impact* | Commercial mechanism |
|---|---|---|
| Long burn-in cycle time | High | Extended stress consumes tester slots and working capital; every added hour must justify a lower failure-escape risk. |
| High power and thermal infrastructure cost | High | AI devices can require expensive power delivery, cooling and facility utilities, raising capital and operating cost per test position. |
| Overkill and correlation risk | Medium–High | Stress that is too aggressive may reject good devices or create non-field-relevant failures, reducing yield and customer confidence. |
| Package and interface churn | Medium | Frequent package changes require new sockets, boards and thermal fixtures, limiting reuse and extending ramp time. |
Test time directly competes with production throughput
Burn-in occupies a device for much longer than many parametric or functional tests. When AI volumes ramp quickly, an unchanged stress duration can require a large increase in parallel capacity, floor space and working capital. Customers therefore pressure equipment vendors to add channels and improve acceleration without losing defect coverage. The market restraint is economic: stronger screening helps reliability, but every hour added to every high-volume device must be justified by avoided field failures or warranty costs.
Power and cooling scale faster than simple channel count
Adding more sockets does not automatically add usable AI burn-in capacity. High-power devices require stable rails, high-current distribution and removal of substantial heat from a compact rack. Facility power and chilled-water infrastructure can become the limiting factor even when testers are available. This raises total cost of ownership and favors platforms designed around energy efficiency, liquid cooling and flexible power allocation rather than systems optimized for lower-power legacy devices.
Poor stress correlation can destroy yield
Burn-in only creates value when the applied stress exposes real early-life weaknesses. If voltage, temperature or workload are too aggressive, good devices may fail the screen even though they would have met field requirements. That false-reject cost is particularly painful for expensive advanced packages. Reliability teams therefore need silicon knowledge, failure analysis and statistical correlation, increasing engineering effort. A test-equipment supplier cannot solve the problem through hardware alone; recipes and data interpretation are equally important.
Fast package evolution raises interface cost
AI packages are changing quickly in size, current demand, memory configuration and cooling strategy. Device interfaces, sockets, load boards and thermal fixtures may need redesign for each major generation. This can limit reuse of installed burn-in infrastructure and extend qualification timelines. Equipment vendors respond with modular platforms and programmable software, but the physical interface remains device-specific. Customers must therefore plan for recurring tooling cost alongside tester depreciation.
MARKET OPPORTUNITIES
Where can suppliers create incremental value?
Liquid-cooled high-parallelism burn-in
As AI devices move beyond what air cooling can handle efficiently, liquid-cooled burn-in platforms can create a differentiated capacity solution. The opportunity is not only to cool one device at higher power but to support many devices in parallel while maintaining consistent junction conditions and power delivery. Equipment suppliers that integrate cooling, monitoring and safety into a scalable rack can reduce the customer’s engineering burden and enable higher test density in existing floor space.
Programmable workload stress and digital-twin-like correlation
Static voltage and temperature screens may miss failures that appear under rapid workload transitions. Programmable load systems can replay power patterns closer to training or inference behavior and combine them with thermal stress. The commercial opportunity is a software-defined platform where customers can update stress profiles as architectures evolve. Suppliers can add analytics that compare production response with known-good signatures, turning burn-in from a fixed recipe into an adaptable reliability workflow.
Integrated data analytics across wafer, package and burn-in test
AI packages generate data at wafer sort, die screening, assembly, burn-in and final test. Linking these records can identify upstream process drift before it creates field failures or expensive downstream rejects. Advantest’s 2025 collaboration around AI-powered semiconductor testing reflects the industry’s interest in using analytics to accelerate decision-making. The opportunity favors vendors that provide open data interfaces and fleet-level software rather than treating each tester as an isolated box.
Regional advanced-packaging capacity in the United States and Asia
New advanced-packaging and test capacity creates greenfield demand for burn-in hardware, interfaces, cooling and engineering services. The U.S. Amkor project and continuing Asian CoWoS and OSAT expansion illustrate both sides of the opportunity. Suppliers that support multiple regions can follow customers as manufacturing footprints diversify, while local field-service capability becomes more important because high-power reliability equipment can interrupt production if support is slow.
AI Chip Burn-in Test Market Supply Chain Analysis
The AI chip burn-in supply chain begins with AI device and package design, moves through sockets, boards, power and thermal subsystems into burn-in/test equipment, and ends with foundry, OSAT, IDM or cloud-led reliability qualification. Value is captured where a supplier removes a production bottleneck or improves failure detection without excessive test time. Because each layer is co-dependent, successful projects involve early engineering exchange rather than a simple catalog equipment purchase.
AI device and package design
Burn-in starts upstream because package current, thermal resistance, memory integration and test access determine what equipment can do. A design team that engages the reliability supply chain early can avoid late fixture constraints and improve observability. The market implication is that winning equipment positions often begin before production qualification. Suppliers that understand package roadmaps and can simulate power and cooling needs gain an advantage over vendors entering only after the hardware is frozen.
Interface and thermal subsystem
Sockets and load boards must deliver large currents, maintain signal integrity and survive repeated thermal cycles. Cooling hardware must keep device temperature within a controlled range even when workload power changes quickly. These components wear and can be highly package specific, creating recurring aftermarket revenue. The bottleneck is lead time: a tester may be ready while a qualified socket or cooling fixture is not, so interface suppliers become critical partners during AI ramp schedules.
Test equipment layer
The equipment platform combines instrumentation, power, switching, thermal control, automation and software. Customers evaluate not only maximum specifications but also parallel efficiency, uptime, calibration, service and upgrade paths. A system that can be reconfigured for several package generations protects customer capital and improves vendor stickiness. As AI power rises, liquid-cooling compatibility and facility integration become differentiators alongside raw electrical performance.
Reliability operations and analytics
Foundries, OSATs and chip companies turn raw tester output into pass/fail decisions and process learning. Linking burn-in failures to wafer position, package lot and field return data can identify systematic weaknesses earlier. Cloud customers can also feed deployment reliability back into screening requirements. This creates an opportunity for common data layers and AI-assisted root-cause analysis, but only if test records are standardized enough to compare across equipment and manufacturing stages.
Recent Developments in the AI Chip Burn-in Test Market
Recent developments demonstrate that AI semiconductor test is moving toward higher power, liquid cooling and AI-assisted analytics, while governments and manufacturers are adding advanced-packaging capacity closer to AI design and deployment centers. The strategic implication is a broader installed-base opportunity for burn-in suppliers, but also a higher technical bar: new platforms must integrate electrical stress, thermal management, data and package-specific interfaces as one production system.
Teradyne’s 2025 annual filing reported an 18.8% increase in semiconductor-test revenue and stated that AI-related demand represented the majority of semiconductor-test revenue in the second half of 2025, with AI expected to remain a major driver in early 2026. The disclosure is important because it provides equipment-vendor evidence that AI is already materially changing test demand, supporting investment in higher-power and advanced-packaging test capability.
Advantest announced work on AI-powered semiconductor testing using its ACS ecosystem and NVIDIA technology. The development matters because burn-in and final-test datasets are becoming too complex for purely manual analysis at AI production scale. Applying AI to test operations can accelerate root-cause identification, improve adaptive test decisions and reduce engineering cycle time, adding a software and analytics layer to the traditional equipment value proposition.
Advantest’s International Test Conference communication highlighted the 7038 platform for system-level and burn-in testing, including support for liquid-cooled environments. The development directly reflects the thermal challenge of AI and HPC devices. Liquid cooling allows higher device power and denser parallel test, but it also requires coordination with facility infrastructure and package fixtures, increasing the value of integrated equipment engineering.
The U.S. Department of Commerce announced a finalized award of up to USD 407 million for Amkor’s advanced packaging and test facility in Arizona. The project is broader than AI burn-in, but it creates domestic infrastructure for advanced packaged semiconductors that require final test and reliability screening. New packaging capacity creates follow-on demand for test platforms, sockets, cooling, automation and skilled field support in North America.
TSMC’s CoWoS technology materials and 2025 annual-report disclosures emphasize advanced packaging for high-performance computing and AI products. For the burn-in market, the relevance is the rising value and complexity of the completed package. As more compute die and high-bandwidth memory are integrated, reliability screening becomes economically more important and thermally more difficult, supporting demand for advanced package-level test and burn-in capacity.
REPORT SCOPE & SEGMENTATION
The scope preserves the report page’s three burn-in types, four application groups, end-user groups, reliability requirements, deployment-scale categories and full profiled company list. The market series keeps the published 2025 and 2034 size anchors and recomputes the consistent 2026–2034 compound rate. Competitive analysis distinguishes direct test-equipment suppliers from packaging/test service providers and chip companies so the company list is not treated as if every participant sells the same product.
| Attribute | Coverage |
|---|---|
| Market | AI Chip Burn-in Test Market |
| Base year | 2025 — USD 850 million |
| Estimated year | 2026 — USD 942.3 million |
| Forecast year | 2034 — USD 2.150 billion |
| Forecast period | 2026–2034 at 10.9% CAGR |
| Geography | North America; Europe; Asia Pacific; South America; Middle East & Africa |
| Type segmentation | Standard Burn-in; Accelerated Stress Burn-in; Programmable Load Burn-in |
| Application segmentation | Data-Center Accelerators; Edge Inference Devices; Autonomous System Controllers; Others |
| Additional segmentation | End User: Cloud Service Providers; OEMs for Autonomous Vehicles; Industrial Automation Firms. Reliability Requirement: Mission-Critical; High-Performance; Cost-Sensitive. Deployment Scale: Large-Scale Data-Centers; Mid-Size Edge Installations; Embedded IoT Devices. |
| Companies profiled | NVIDIA Corporation; Intel Corporation (Habana Labs); TSMC; Advanced Semiconductor Engineering (ASE); Advantest Corporation; Qualcomm Technologies, Inc.; Samsung Electronics Co., Ltd.; AMD; GlobalFoundries Inc.; Marvell Technology Group Ltd.; Broadcom Inc.; Texas Instruments Inc.; Lattice Semiconductor Corporation |
| Units | Revenue values in USD; technical and commercial metrics are stated with their original units and periods where cited. |
Frequently Asked Questions
What is the AI Chip Burn-in Test Market size in 2025 and 2034?
The report page publishes USD 850 million for 2025 and USD 2.15 billion for 2034. Those anchors are preserved in the standardized series. The implied compound annual growth rate is 10.9% for 2026–2034, and the 2026 estimated value is USD 942.3 million. Using the anchor-derived rate keeps the headline figures internally consistent, rather than carrying forward a rounded percentage that does not exactly reproduce the published 2025 and 2034 market values.
What is AI chip burn-in testing?
AI chip burn-in is a reliability-screening process in which accelerators, processors or related high-performance devices are operated under controlled thermal and electrical stress for an extended period to expose early-life failures before field deployment. The method is especially important for high-value AI packages because a latent defect can disrupt expensive data-center or autonomous-system hardware. Modern implementations increasingly need high-current delivery, precise thermal control, programmable workloads and analytics rather than a simple constant-temperature chamber.
Which burn-in test types are included in the report?
The report page lists Standard Burn-in, Accelerated Stress Burn-in and Programmable Load Burn-in. Standard burn-in is the broadest baseline screen. Accelerated stress methods use stronger controlled conditions to expose weaknesses faster, while programmable-load systems reproduce changing electrical demand more like a real AI workload. Each method has a different balance of test time, defect coverage and overkill risk, so customers select recipes based on device value, reliability target and package behavior.
Which application segment leads the market?
Data-Center Accelerators are treated as the leading application because they combine high device value, high power density and demanding uptime expectations. A failed GPU or AI ASIC can remove compute capacity from a large cluster and require service intervention, so customers have a strong economic incentive to catch early-life weaknesses before deployment. Edge Inference Devices, Autonomous System Controllers and Other applications are also covered, but their unit economics and field environments create different test-intensity requirements.
Which region leads the AI Chip Burn-in Test Market?
North America is used as the largest market in 2025 because the report page’s regional analysis states that the United States currently dominates. Asia Pacific is identified as the fastest-growing region and is positioned to become the largest as foundry, HBM, advanced packaging and OSAT capacity expands. The report page’s FAQ separately says no dominant region is specified, so the regional narrative is treated as the more detailed and directly relevant statement for this overview.
How does advanced packaging affect burn-in demand?
Advanced packaging increases the value and complexity of the device being screened. AI packages can combine several logic die and high-bandwidth-memory stacks, so a defect discovered after final integration can scrap a much more expensive assembly than a single die. CoWoS and similar platforms also raise thermal density. Burn-in therefore needs stronger power delivery, better cooling and package-specific fixtures, increasing both equipment complexity and the economic value of detecting weak devices before system deployment.
What evidence shows AI is increasing semiconductor test demand?
Teradyne’s 2025 annual filing reported that semiconductor-test revenue increased 18.8% and that AI-related demand represented the majority of semiconductor-test revenue in the second half of 2025. These are company results rather than the size of the AI burn-in market, but they provide direct evidence that AI is materially influencing test-equipment demand. Advantest has also highlighted AI/HPC test platforms, liquid-cooling support and AI-assisted test analytics in 2025 product communications.
Which companies are profiled in the AI Chip Burn-in Test Market report?
The report page profiles NVIDIA, Intel through Habana Labs, TSMC, ASE, Advantest, Qualcomm, Samsung, AMD, GlobalFoundries, Marvell, Broadcom, Texas Instruments and Lattice Semiconductor. They play different roles. Advantest is a direct test-equipment supplier, ASE provides packaging and test services, foundries manufacture devices, and many of the remaining companies design or supply chips whose architectures create the burn-in requirement. Competitive analysis should therefore distinguish equipment, service and demand-side participants.
What are the main restraints on market growth?
The main restraints are long burn-in cycle times, high capital and energy cost, thermal-management requirements, package-specific tooling and the risk of over-screening. A stronger stress recipe can catch more weak devices but may also reject good devices if correlation is poor. AI chips intensify the trade-off because they draw large currents and generate substantial heat. Customers need platforms that increase parallelism and realistic stress coverage without making test time or facility infrastructure the limiting production step.
What should suppliers watch through 2034?
Suppliers should track AI accelerator power, HBM and chiplet packaging, liquid-cooled test adoption, programmable workload stress, socket and interface requirements, advanced-packaging capacity expansion and analytics that connect wafer, package, burn-in and field data. The market will reward solutions that reduce the total cost of reliability rather than simply increasing stress severity. Strong local applications engineering in North America and Asia Pacific will remain critical because device ramps require package-specific fixtures, cooling and correlation work.
Research Sources & Evidence Base
Get Sample Report PDF for Exclusive Insights
Report Sample Includes
- Table of Contents
- List of Tables & Figures
- Charts, Research Methodology, and more...
 Download Sample Report PDF