Key Statistics
Key Takeaways
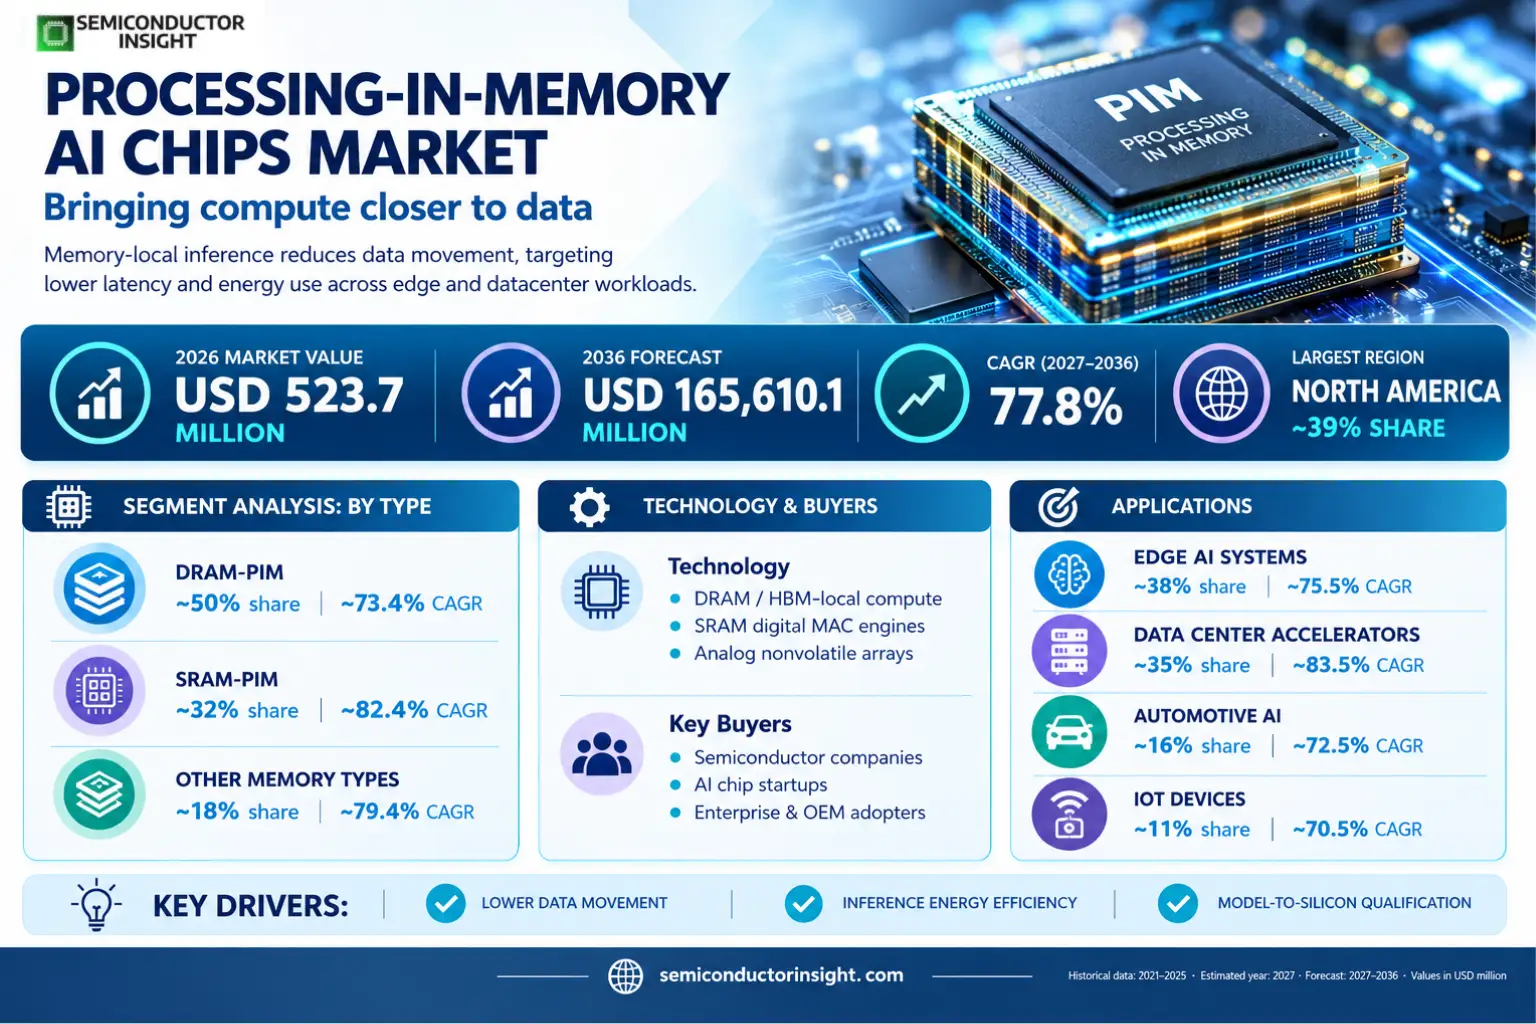
- Market outlook: processing-in-memory ai chips is valued at USD 523.7 million in 2026 and is projected to reach USD 165,610.1 million in 2036, implying a 77.8% compound annual rate for the 2027–2036 forecast period as buyers qualify more production-ready systems rather than prototypes.
- DRAM-PIM leads: The leading Type accounts for an estimated ~50% of 2026 revenue. SRAM-PIM is the fastest-growing Type at ~82.4% CAGR, reflecting product design choices, application power budgets and the economics of qualified manufacturing.
- Edge AI Systems application: This application represents an estimated ~38% of the 2026 market, while Data Center Accelerators shows the strongest long-term growth at ~83.5% CAGR because deployment decisions directly affect supplier production orders.
- North America leads: At an estimated ~39% of 2026 revenue, North America has the leading market position; Asia-Pacific grows fastest at ~80.3% CAGR as spending shifts to commercially deployable technology.
- Principal restraint: For memory-local AI inference silicon, the largest commercial obstacle is turning engineering performance into repeatable field-qualified shipments. Buyers still assess yield, thermal and power characteristics, integration expense, service commitments and the lifetime reliability of edge vision inference.
Processing-in-Memory AI Chips Market Overview
Processing-in-memory ai chips market was valued at USD 523.7 million in 2026 and is projected to reach USD 165,610.1 million by 2036, expanding at a CAGR of 77.8% during 2027–2036. North America is the largest modeled buying region at an estimated ~39% of 2026 revenue. Processing-in-memory hardware must demonstrate usable silicon yield, numerical accuracy and reproducible workload acceleration before pilot deployments translate into sustained annual chip sales.
Processing-in-memory architecture reduces energy and latency spent repeatedly moving neural-network weights between conventional storage and compute units. Dedicated PIM products can use arithmetic embedded within DRAM arrays, digital multiply-accumulate engines integrated around SRAM blocks, or mixed-signal nonvolatile arrays performing computation through device physics. The revenue boundary includes chips that actually execute inference operations within or at the memory fabric, and does not add standard DRAM chips, unrelated GPUs or complete servers to the total. Samsung previously demonstrated HBM-PIM integrated into an accelerator system, confirming the technology path while not establishing broad commercial shipment rates.
DRAM-PIM typically builds on high-density storage and the existing memory-manufacturing supply chain. SRAM-focused digital in-memory computing offers a contrasting strategy: small-batch inference can benefit from tightly coupled operands and low internal data movement, but capacity may be expensive compared with DRAM. d-Matrix reported in June 2026 that its Corsair inference platform entered full production using SRAM-based digital in-memory compute chiplets. The statement confirms a supplier production milestone; it does not mean its entire rack price should be treated as PIM chip sales. Chip-level counts must distinguish packaged accelerators from higher-value server deployments.
Nonvolatile analog processing adds another branch to the market. IBM Research has demonstrated phase-change-memory arrays performing matrix-vector operations and 64-core analog in-memory computation, with mixed digital processing needed for nonlinear and control functions. IBM publications in 2025 also describe constraints from quantization, stochastic device variation and software mapping. These caveats matter commercially because an energy-saving matrix kernel is only valuable when the entire model reaches acceptable accuracy, throughput and reliability. Buyers therefore compare full end-to-end inference metrics rather than stand-alone operations-per-second demonstrations.
Hardware investment is expanding but has not removed commercialization risks. Mythic announced financing in December 2025 for its analog computing platform; d-Matrix announced an Alchip collaboration on 3D DRAM inference in November 2025; and EnCharge AI has described analog capacitor-based computation in standard CMOS processes. These represent distinct technical families with different memory scaling, programming and production challenges. They also make the supplier landscape difficult to summarize using a single benchmark, because analog flash, SRAM-DIMC, HBM-PIM and phase-change technologies do not share identical precision, endurance or system constraints.
The high headline growth rate is largely a statement about the starting level of commercial adoption, not proof of a finished mass market. Early qualified AI inference chips may grow rapidly from limited deployment into larger edge and datacenter programs, while programming tools, yield and integration determine the pace. IBM Research identifies the difficulty of mapping complex models onto heterogeneous analog/digital accelerator fabrics; memory manufacturers also face qualification cycles different from software startups. Regional demand is concentrated where device-design investment and memory fabrication coincide, particularly North America and Asia-Pacific. These are market estimates and should not be treated as a published count of PIM-unit shipments.
Segment Analysis: By Type
By Type, processing-in-memory ai chips is divided into DRAM-PIM, SRAM-PIM, Other Memory Types. DRAM-PIM has the largest modeled share, an estimated ~50% in 2026; SRAM-PIM grows fastest at ~82.4% CAGR. For memory-local AI inference silicon, each category is counted once on the primary product specification, so overlapping design functions are not added as independent revenue streams.
| Type | Function | Market position |
|---|---|---|
| DRAM-PIM | Processing logic integrated with DRAM or stacked high-bandwidth memory, designed for bandwidth-sensitive matrix operations and large model weights.. This design is relevant to edge vision inference and adjacent qualified uses where measurable performance is critical. The DRAM-PIM qualification program tests integration tolerances, supply-chain dependency and reliability before volume manufacture. For processing-in-memory ai chips, the practical commercial question is whether DRAM-PIM can be sustained at the purchase volumes implied by the specified product category. Qualification for DRAM-PIM requires an executable order forecast as well as suitable testing capacity and lifecycle support. The DRAM-PIM purchase decision for DRAM-PIM therefore affects supplier selection, unit economics and deployment timing rather than just the volume of demonstrations. | DRAM-PIM is the largest assumed class because memory makers can extend established DRAM manufacturing processes and capacity. Estimated 2026 type share is ~50%, with modeled growth of ~73.4% CAGR. For DRAM-PIM sourcing, buyers compare the full device bill of materials, operating constraints and vendor software or optics support before awarding high-volume orders. |
| SRAM-PIM | Digital multiply-accumulate compute performed alongside or inside SRAM storage structures on a dedicated accelerator die.. This design is relevant to memory-centric cloud inference and adjacent qualified uses where measurable performance is critical. The SRAM-PIM qualification program tests integration tolerances, supply-chain dependency and reliability before volume manufacture. For processing-in-memory ai chips, the practical commercial question is whether SRAM-PIM can be sustained at the purchase volumes implied by the specified product category. Qualification for SRAM-PIM requires an executable order forecast as well as suitable testing capacity and lifecycle support. The SRAM-PIM purchase decision for SRAM-PIM therefore affects supplier selection, unit economics and deployment timing rather than just the volume of demonstrations. | SRAM-PIM provides low-latency execution for interactive inference but pays a silicon-density penalty relative to DRAM. Estimated 2026 type share is ~32%, with modeled growth of ~82.4% CAGR. For SRAM-PIM sourcing, buyers compare the full device bill of materials, operating constraints and vendor software or optics support before awarding high-volume orders. |
| Other Memory Types | Nonvolatile phase-change, ReRAM and other analog charge-storage arrays used for matrix computations near stationary neural weights.. This design is relevant to autonomous vision modules and adjacent qualified uses where measurable performance is critical. The Other Memory Types qualification program tests integration tolerances, supply-chain dependency and reliability before volume manufacture. For processing-in-memory ai chips, the practical commercial question is whether Other Memory Types can be sustained at the purchase volumes implied by the specified product category. Qualification for Other Memory Types requires an executable order forecast as well as suitable testing capacity and lifecycle support. The Other Memory Types purchase decision for Other Memory Types therefore affects supplier selection, unit economics and deployment timing rather than just the volume of demonstrations. | Alternative memory arrays remain smaller but offer potential gains in inference energy per operation subject to noise, endurance and process qualification. Estimated 2026 type share is ~18%, with modeled growth of ~79.4% CAGR. For Other Memory Types sourcing, buyers compare the full device bill of materials, operating constraints and vendor software or optics support before awarding high-volume orders. |
Secondary segmentation: By End User
By End User is an additional qualitative classification of processing-in-memory ai chips; its members are Semiconductor Companies, Tech Startups, Research Institutions, Enterprise AI Adopters. Semiconductor device developers lead early qualification, while enterprise acceptance depends on software portability. These categories describe where hardware is used or the optical approach chosen. For memory-local AI inference silicon, they are not additive market totals and retain their original distinctions in purchasing and competitive analysis.
| Axis | Members | Commercial role |
|---|---|---|
| By End User | Semiconductor Companies · Tech Startups · Research Institutions · Enterprise AI Adopters | Semiconductor device developers lead early qualification, while enterprise acceptance depends on software portability. The subgroups include Semiconductor Companies, Tech Startups, Research Institutions, Enterprise AI Adopters. Processing-in-memory suppliers serve different commercialization stages, from device R&D and memory wafer fabrication to customer qualification for neural-network inference. A research program is not an end-user shipment until usable silicon is delivered. |
Secondary segmentation: By Architecture
By Architecture is an additional qualitative classification of processing-in-memory ai chips; its members are Near-Memory Computing, In-Memory Processing, Compute-in-Memory. Near-memory is adjacent to arrays, whereas in-memory forms execute selected arithmetic within or across memory cells. These categories describe where hardware is used or the optical approach chosen. For factory-ramp planning in the processing-in-memory ai chips market, they are not additive market totals and retain their original distinctions in purchasing and competitive analysis. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
| Axis | Members | Commercial role |
|---|---|---|
| By Architecture | Near-Memory Computing · In-Memory Processing · Compute-in-Memory | Near-memory is adjacent to arrays, whereas in-memory forms execute selected arithmetic within or across memory cells. The subgroups include Near-Memory Computing, In-Memory Processing, Compute-in-Memory. For processing-in-memory devices, the location of arithmetic execution relative to the memory cell array is critical to product classification; buyer qualification centers on precision, endurance and memory bandwidth rather than a shared hardware branding term. |
Secondary segmentation: By Precision
By Precision is an additional qualitative classification of processing-in-memory ai chips; its members are Low-Precision (4-8 bit), Medium-Precision (8-16 bit), High-Precision (32+ bit). The permitted numerical precision determines quantization error, area, compute density and application suitability. These categories describe where hardware is used or the optical approach chosen. For OEM sourcing negotiations in the processing-in-memory ai chips market, they are not additive market totals and retain their original distinctions in purchasing and competitive analysis. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
| Axis | Members | Commercial role |
|---|---|---|
| By Precision | Low-Precision (4-8 bit) · Medium-Precision (8-16 bit) · High-Precision (32+ bit) | The permitted numerical precision determines quantization error, area, compute density and application suitability. The subgroups include Low-Precision (4-8 bit), Medium-Precision (8-16 bit), High-Precision (32+ bit). A purchaser evaluating by precision must match the subcategory to environmental qualifications, image accuracy, unit-cost targets and deployment support; the same unit is not counted again simply because it serves multiple end-users. |
Segment Analysis: By Application
By Application, the market includes Edge AI Systems, Data Center Accelerators, Automotive AI Processors, IoT Devices. Edge AI Systems represents the largest estimated 2026 share at ~38%; Data Center Accelerators is modeled to rise at ~83.5% CAGR. For memory-local AI inference silicon, differences in application certification, sales cycle and installation economics produce distinct buying patterns even where suppliers use a common device family.
| Application | Demand characteristics |
|---|---|
| Edge AI Systems | Estimated ~38% of 2026 market revenue; ~75.5% CAGR. Edge AI Systems buyers use edge vision inference to meet operational objectives that must be converted into equipment specifications. For memory-local AI inference silicon, engineering teams evaluate device lifetime, local power, image or inference quality and available integrators, then qualify the component before placing a production order. Edge AI Systems production calendars differ from the prototype stage because volume procurement depends on budget approval, field reliability and long-term supplier commitments. |
| Data Center Accelerators | Estimated ~35% of 2026 market revenue; ~83.5% CAGR. Data Center Accelerators buyers use memory-centric cloud inference to meet operational objectives that must be converted into equipment specifications. For product lifecycle qualification in the processing-in-memory ai chips market, engineering teams evaluate device lifetime, local power, image or inference quality and available integrators, then qualify the component before placing a production order. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Data Center Accelerators production calendars differ from the prototype stage because volume procurement depends on budget approval, field reliability and long-term supplier commitments. |
| Automotive AI Processors | Estimated ~16% of 2026 market revenue; ~72.5% CAGR. Automotive AI Processors buyers use autonomous vision modules to meet operational objectives that must be converted into equipment specifications. For near-term purchasing cycles in the processing-in-memory ai chips market, engineering teams evaluate device lifetime, local power, image or inference quality and available integrators, then qualify the component before placing a production order. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Automotive AI Processors production calendars differ from the prototype stage because volume procurement depends on budget approval, field reliability and long-term supplier commitments. |
| IoT Devices | Estimated ~11% of 2026 market revenue; ~70.5% CAGR. IoT Devices buyers use embedded sensor analytics to meet operational objectives that must be converted into equipment specifications. For field reliability evaluation in the processing-in-memory ai chips market, engineering teams evaluate device lifetime, local power, image or inference quality and available integrators, then qualify the component before placing a production order. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. IoT Devices production calendars differ from the prototype stage because volume procurement depends on budget approval, field reliability and long-term supplier commitments. |
Application mix governs distribution strategy as much as production engineering. For memory-local AI inference silicon, professional buyers frequently procure through specialist OEMs, equipment makers and trained system integrators rather than from component manufacturers directly. For memory-local AI inference silicon, consumer device vendors negotiate consolidated volume terms, whereas industrial and regulated applications demand documentation and spare-part assurances. For memory-local AI inference silicon, consequently, a supplier may win a lucrative design without recording shipments until the downstream device launches. Qualified channels provide the link from the published addressable market to actual hardware purchases.
Regional Analysis
North America leads the processing-in-memory ai chips market with an estimated ~39% of 2026 revenue, followed by Asia-Pacific (~36%) and Europe (~17%). Asia-Pacific has the highest modeled regional growth at ~80.3% CAGR. For memory-local AI inference silicon, regional economic logic reflects where the relevant devices are bought or installed, and it does not equate the geographic location of a corporate headquarters with consumption.
Why does processing-in-memory ai chips demand vary between regional buying centers?
For memory-local AI inference silicon, geographic purchase behavior is driven by the location of finished-device orders, local application ecosystems and supplier qualification routes. For memory-local AI inference silicon, a sophisticated prototype designed in one country may be manufactured in another and installed in a third; these activities are not three independent sales of the same module or chipset. For memory-local AI inference silicon, therefore the regional revenue split reflects purchasing and deployment assumptions rather than allocating the whole corporate sales of firms operating internationally. Fast-growing regions can also start from much smaller installation bases. Comparisons should examine procurement triggers alongside the stated estimated share and growth.
| Region | Position | Growth outlook | Demand profile | What decides supplier selection |
|---|---|---|---|---|
| North America | #1 (~39%) | ~78.3% CAGR | Ai semiconductor architecture and enterprise compute purchasing | United States: qualification and buyer access |
| Asia-Pacific | #2 (~36%) | ~80.3% CAGR | Semiconductor manufacturing and platform integration | China: qualification and buyer access |
| Europe | #3 (~17%) | ~72.3% CAGR | Industrial ai integration and scientific compute | Germany: qualification and buyer access |
| Middle East & Africa | #4 (~5%) | ~75.3% CAGR | Sovereign compute investments and deployment partnerships | United Arab Emirates: qualification and buyer access |
| South America | #5 (~3%) | ~69.3% CAGR | Regional cloud capacity and specialized enterprise pilots | Brazil: qualification and buyer access |
Competitive Landscape
Competition in processing-in-memory ai chips depends on the delivered hardware and usable software ecosystem, not on generalized AI accelerator spending. For memory-local AI inference silicon, the market includes suppliers with distinct roles across processor intellectual property, dedicated silicon, hardware cards and integration services. For memory-local AI inference silicon, commercial positions therefore require product-by-product verification, customer qualification and clear differentiation between prototype announcements and material volume deployments. For memory-local AI inference silicon, technical standards and adjacent device revenues are important context, but they do not independently establish manufacturer market shares.
Processing-in-memory suppliers are differentiated by what is physically computed at the storage element. Samsung and SK hynix have developed memory-side processing concepts, d-Matrix uses SRAM-based digital in-memory compute, and Mythic and EnCharge AI pursue distinct analog techniques. These architectures cannot be ranked solely by generic AI TOPS claims because model accuracy, precision, memory capacity, external bandwidth and software support vary materially. Companies offering conventional neural processors are adjacent unless the memory-local execution mechanism is specifically documented.
Manufacturing capabilities are distributed unevenly across the ecosystem. Korean DRAM companies possess high-volume memory fabrication expertise and package assembly relationships; US startups often depend on outsourced semiconductor production and focused software teams. IBM Research contributes published demonstrations of phase-change-memory inference and software mapping rather than claiming broad merchant PIM chip shipments. Consequently, a list of technical participants does not establish how much commercial revenue is attributable to each firm.
d-Matrix disclosed June 2026 full production of Corsair and described its SRAM-based inference compute chiplets, while the company and Alchip announced exploratory 3D DRAM technology in November 2025. The transition from research tape-out to contracted production is significant, but it still requires examining the output sold: a bare accelerator die, packaged card or complete rack. Market-share models must not count all three layers as separate sales; enterprise procurement and specialized customer integration can substantially alter the reported selling price.
Analog inference faces signal variation, conversion overhead and quantization constraints that do not affect conventional digital logic in the same way. IBM Research publications in 2025 discuss both neural-network mapping and noise-aware adaptation, underscoring the importance of end-to-end performance rather than laboratory cell efficiency. The strongest commercial competitors will pair architecture differentiation with usable development frameworks, product warranty, enough production volume and a supported roadmap. These requirements remain meaningful restraints on exceptional headline market-growth scenarios.
Tier structure
| Tier | Companies | Basis of competition |
|---|---|---|
| Dedicated compute-in-memory chips | d-Matrix; Mythic; EnCharge AI; Witmem Technology | Memory-local arithmetic or mixed-signal AI execution with product-specific qualification. For memory-local AI inference silicon, supplier shares should distinguish the shipped add-in chip or card from licensing, research and higher-value integrated systems. For memory-local AI inference silicon, in procurement, engineers also evaluate driver support, memory access patterns, thermal stability, production testing capability, software support and the sustainability of the product roadmap before awarding recurring contracts. |
| Memory and research developers | Samsung; SK hynix; IBM Research | PIM memory architecture, DRAM integration, analog device physics and research prototypes. For component yield verification in the processing-in-memory ai chips market, supplier shares should distinguish the shipped add-in chip or card from licensing, research and higher-value integrated systems. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For deployment risk assessment in the processing-in-memory ai chips market, in procurement, engineers also evaluate driver support, memory access patterns, thermal stability, production testing capability, software support and the sustainability of the product roadmap before awarding recurring contracts. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. |
| Adjacent and exploratory systems | Syntiant; Graphcore; Axelera AI; Reexen Technology | Neural acceleration or architecture design participants requiring direct PIM product verification. For regional distribution planning in the processing-in-memory ai chips market, supplier shares should distinguish the shipped add-in chip or card from licensing, research and higher-value integrated systems. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For technical product validation in the processing-in-memory ai chips market, in procurement, engineers also evaluate driver support, memory access patterns, thermal stability, production testing capability, software support and the sustainability of the product roadmap before awarding recurring contracts. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. |
Key companies profiled
- Syntiant
- Hangzhou Zhicun (Witmem) Technology
- Shenzhen Reexen Technology
- Mythic
- Beijing Pingxin Technology
- Graphcore
- Axelera AI
- AistarTek
- Suzhou Yizhu Intelligent Technology
- Beijing Houmo Technology
- Samsung
- SK hynix
- d-Matrix
- EnCharge AI
Production Capacity Analysis
For memory-local AI inference silicon, capacity should be understood as qualified, saleable units rather than nominal wafer, substrate or assembled-board throughput. For memory-local AI inference silicon, prototype line availability can overstate capacity when testing yield, packaging or customer-acceptance requirements are excluded. For memory-local AI inference silicon, the production constraint moves across process steps as designs mature: upstream materials, chip fabrication or optical processing, final assembly and system qualification. An announced factory expansion is an indicator of potential supply rather than proof of sales. Supply decisions require both process capability and downstream purchase orders.
Qualified fabrication and tested package throughput matter more than nominal semiconductor capacity for processing-in-memory ai chips. For memory-local AI inference silicon, production involves wafer design, mask qualification, foundry processing, wafer probe, package assembly, reliability testing and a qualified delivery route. For memory-local AI inference silicon, different architectures emphasize different bottlenecks: memory-array stability for PIM, die-to-die yield for chiplets and board-level cooling for PCIe cards. For memory-local AI inference silicon, companies may operate development teams in one geography while purchasing fabrication from foundries elsewhere, so corporate headquarters are not an adequate proxy for region of manufacture.
Engineering capacity translates into contracted processing-in-memory ai chips output only when software, boards and customer performance requirements converge. For memory-local AI inference silicon, supplier documentation commonly outlines a launch, sampling stage or reference design rather than audited monthly shipped quantities. For memory-local AI inference silicon, production ramps can be delayed by packaging substrate constraints, firmware defects, yield excursions or customer redesigns. For memory-local AI inference silicon, system integrators may already have card installation capacity but be blocked by accelerator memory supply; similarly an approved AI chip can remain unsold while an OEM validates its application model. These differences materially influence revenue timing.
The manufacturing supply chain for processing-in-memory ai chips is exposed to foundry concentration, testing costs, specialized packaging and global logistics. For memory-local AI inference silicon, regional companies have different strengths: US design and software, Asian semiconductor wafer and memory manufacture, European industrial qualification and a globally distributed customer base. For memory-local AI inference silicon, customers therefore negotiate product traceability, alternative component sources, order cancellation rights and sustained driver support. For memory-local AI inference silicon, a second source is commercially useful only after equivalent performance, reliability and revision compatibility have been demonstrated, often requiring further engineering expense.
Market Dynamics
For memory-local AI inference silicon, growth is being shaped by a chain of events, from application requirements through device architecture and manufacturing availability to procurement. For memory-local AI inference silicon, drivers increase the probability that a buyer approves a qualified hardware platform, whereas restraints lower the attainable deployment rate or the price achieved per shipped component. Opportunities arise where a technical capability solves a measurable task at a competitive total cost. Impact figures below are directional scenario sensitivities, not independent published market statistics. They are assessed individually and are not additive to the headline CAGR.
MARKET DRIVERS
Drivers Impact Analysis*
| Driver | (~) % impact on CAGR forecast | Geographic relevance | Impact timeline |
|---|---|---|---|
| memory-local matrix multiplication adoption | +1.8% | Global compute projects | 2027–2036 |
| analog quantization accuracy adoption | +1.4% | Semiconductor engineering centers | 2027–2036 |
| memory array endurance adoption | +1.1% | Enterprise AI deployments | 2027–2036 |
| PIM compiler interoperability adoption | +0.8% | Regional system manufacturers | 2027–2036 |
| AI application procurement | +0.6% | Global | 2027–2033 |
Memory-Local Matrix Multiplication
Memory-Local Matrix Multiplication shapes technical purchasing decisions for processing-in-memory ai chips, particularly when architecture choice can reduce bottlenecks in a real application. For memory-local AI inference silicon, engineers must prove performance under representative workload sizes and power budgets rather than relying on marketing benchmarks. For memory-local AI inference silicon, supplier documentation and qualification evidence determine whether the feature can be integrated into a production system. Regional budgets and available system integrators influence the timing of actual equipment orders. For memory-local AI inference silicon, the result is a growth driver contingent on reliable implementation and maintainable software rather than a guaranteed increase in industry-wide chip shipments.
Analog Quantization Accuracy
Analog Quantization Accuracy shapes technical purchasing decisions for processing-in-memory ai chips, particularly when architecture choice can reduce bottlenecks in a real application. For factory-ramp planning in the processing-in-memory ai chips market, supplier documentation and qualification evidence determine whether the feature can be integrated into a production system. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Regional budgets and available system integrators influence the timing of actual equipment orders.
Memory Array Endurance
Memory Array Endurance shapes technical purchasing decisions for processing-in-memory ai chips, particularly when architecture choice can reduce bottlenecks in a real application. For OEM sourcing negotiations in the processing-in-memory ai chips market, supplier documentation and qualification evidence determine whether the feature can be integrated into a production system. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Regional budgets and available system integrators influence the timing of actual equipment orders.
Pim Compiler Interoperability
Pim Compiler Interoperability shapes technical purchasing decisions for processing-in-memory ai chips, particularly when architecture choice can reduce bottlenecks in a real application. For product lifecycle qualification in the processing-in-memory ai chips market, supplier documentation and qualification evidence determine whether the feature can be integrated into a production system. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Regional budgets and available system integrators influence the timing of actual equipment orders.
MARKET RESTRAINTS
Restraints Impact Analysis*
| Restraint | (~) % impact on CAGR forecast | Geographic relevance | Impact timeline |
|---|---|---|---|
| Product qualification complexity | −1.6% | Global OEM programs | 2027–2031 |
| Memory and packaging limits | −1.2% | Advanced manufacturing centers | 2027–2036 |
| Software migration cost | −0.9% | Cloud and embedded systems | 2027–2036 |
| Supply and export constraints | −0.7% | Cross-border procurement | 2027–2036 |
Product qualification complexity
Product qualification complexity is a material limitation on processing-in-memory ai chips implementation because customers need traceable evidence of reliability, production capacity and application compatibility. For memory-local AI inference silicon, additional engineering validation can require multiple silicon or firmware revisions, while complex programs may use more than one supplier under strict change controls. For memory-local AI inference silicon, an architectural advantage on one benchmark does not offset the cost of requalification and ongoing security maintenance. For memory-local AI inference silicon, buyers may respond by delaying deployment, reducing initial volumes or retaining mature alternative platforms, producing a slower commercial adoption path than product demonstrations imply.
Memory and packaging limits
Memory and packaging limits is a material limitation on processing-in-memory ai chips implementation because customers need traceable evidence of reliability, production capacity and application compatibility. For near-term purchasing cycles in the processing-in-memory ai chips market, additional engineering validation can require multiple silicon or firmware revisions, while complex programs may use more than one supplier under strict change controls. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For field reliability evaluation in the processing-in-memory ai chips market, buyers may respond by delaying deployment, reducing initial volumes or retaining mature alternative platforms, producing a slower commercial adoption path than product demonstrations imply. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
Software migration cost
Software migration cost is a material limitation on processing-in-memory ai chips implementation because customers need traceable evidence of reliability, production capacity and application compatibility. For device cost-down programs in the processing-in-memory ai chips market, additional engineering validation can require multiple silicon or firmware revisions, while complex programs may use more than one supplier under strict change controls. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For contract manufacturing qualification in the processing-in-memory ai chips market, buyers may respond by delaying deployment, reducing initial volumes or retaining mature alternative platforms, producing a slower commercial adoption path than product demonstrations imply. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
Supply and export constraints
Supply and export constraints is a material limitation on processing-in-memory ai chips implementation because customers need traceable evidence of reliability, production capacity and application compatibility. For multi-year supply agreements in the processing-in-memory ai chips market, additional engineering validation can require multiple silicon or firmware revisions, while complex programs may use more than one supplier under strict change controls. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For component yield verification in the processing-in-memory ai chips market, buyers may respond by delaying deployment, reducing initial volumes or retaining mature alternative platforms, producing a slower commercial adoption path than product demonstrations imply. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
MARKET OPPORTUNITIES
Memory-Local Matrix Multiplication expansion
The strongest opportunity linked to memory-local matrix multiplication is to deliver measurable improvement in a clearly defined AI or compute workload with a full qualified system pathway. For memory-local AI inference silicon, technical viability needs to be reflected in documented latency, power, memory capacity and production yield. Device makers must be able to access development tools and identify long-term chip availability. For memory-local AI inference silicon, smaller system firms can compete by specializing the software integration or reference design instead of repeating general-purpose hardware. This creates scope for focused commercial contracts even where total market growth remains uncertain.
Analog Quantization Accuracy expansion
The strongest opportunity linked to analog quantization accuracy is to deliver measurable improvement in a clearly defined AI or compute workload with a full qualified system pathway. Device makers must be able to access development tools and identify long-term chip availability. For deployment risk assessment in the processing-in-memory ai chips market, smaller system firms can compete by specializing the software integration or reference design instead of repeating general-purpose hardware. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. This creates scope for focused commercial contracts even where total market growth remains uncertain.
Memory Array Endurance expansion
The strongest opportunity linked to memory array endurance is to deliver measurable improvement in a clearly defined AI or compute workload with a full qualified system pathway. Device makers must be able to access development tools and identify long-term chip availability. For regional distribution planning in the processing-in-memory ai chips market, smaller system firms can compete by specializing the software integration or reference design instead of repeating general-purpose hardware. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. This creates scope for focused commercial contracts even where total market growth remains uncertain.
Pim Compiler Interoperability expansion
The strongest opportunity linked to PIM compiler interoperability is to deliver measurable improvement in a clearly defined AI or compute workload with a full qualified system pathway. Device makers must be able to access development tools and identify long-term chip availability. For technical product validation in the processing-in-memory ai chips market, smaller system firms can compete by specializing the software integration or reference design instead of repeating general-purpose hardware. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. This creates scope for focused commercial contracts even where total market growth remains uncertain.
Supply Chain Analysis
The processing-in-memory ai chips supply chain begins with semiconductor architecture and device intellectual property, passes through fabrication and packaging, and reaches an OEM or systems integrator through a qualified software-and-hardware channel. For memory-local AI inference silicon, final applications may be sold as servers, appliances or embedded products, but the hardware value must be counted only once at the defined chip or card boundary. For memory-local AI inference silicon, export requirements, component traceability and long-term tool support shape commercial access across regions.
Upstream. Upstream activities determine the practical procurement pathway for processing-in-memory ai chips: Silicon IP, electronic design automation, wafers, specialized memory and packaging substrates. For memory-local AI inference silicon, a qualified system requires documented performance and revision-control procedures at this stage, even when the device technology is based on a common open standard. For memory-local AI inference silicon, commercial risk rises when a single input has a long fabrication lead time or lacks a validated substitute. For memory-local AI inference silicon, each partner therefore needs workable engineering escalation, repair responsibilities and long-term product support. For memory-local AI inference silicon, the resulting supply arrangement affects contract timing, availability and warranty costs without representing a separate new market whenever the same silicon moves between companies.
Manufacturing. Manufacturing activities determine the practical procurement pathway for processing-in-memory ai chips: Foundry wafer production, memory integration, assembly, burn-in, board testing and reliability qualification. For factory-ramp planning in the processing-in-memory ai chips market, commercial risk rises when a single input has a long fabrication lead time or lacks a validated substitute. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For OEM sourcing negotiations in the processing-in-memory ai chips market, the resulting supply arrangement affects contract timing, availability and warranty costs without representing a separate new market whenever the same silicon moves between companies. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
Channel. Channel activities determine the practical procurement pathway for processing-in-memory ai chips: Processor vendors, OEM manufacturing partners, server integrators, authorized distributors and software developers. For product lifecycle qualification in the processing-in-memory ai chips market, commercial risk rises when a single input has a long fabrication lead time or lacks a validated substitute. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For near-term purchasing cycles in the processing-in-memory ai chips market, the resulting supply arrangement affects contract timing, availability and warranty costs without representing a separate new market whenever the same silicon moves between companies. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
Downstream. Downstream activities determine the practical procurement pathway for processing-in-memory ai chips: Data centers, industrial edge installations, vehicle computing programs and specialized scientific workloads. For field reliability evaluation in the processing-in-memory ai chips market, commercial risk rises when a single input has a long fabrication lead time or lacks a validated substitute. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For device cost-down programs in the processing-in-memory ai chips market, the resulting supply arrangement affects contract timing, availability and warranty costs without representing a separate new market whenever the same silicon moves between companies. This consideration continues to affect customer decisions across the 2026–2036 planning horizon.
Recent Developments
- 9 June 2026 Announced
d-Matrix — Corsair inference production. The 9 June 2026 company release documents a specific step in semiconductor architecture, standards, AI software or system integration. For processing-in-memory ai chips, its relevance is the effect on qualification work, possible supplier choices and the ability to deliver a supported compute product. For memory-local AI inference silicon, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. For memory-local AI inference silicon, hardware buyers also need stable software tools, a defensible energy and performance profile and a supplier able to maintain the design through multiple production cycles. Source - 16 March 2026 Published
d-Matrix — 3D DRAM memory-centric inference. The 16 March 2026 company engineering note documents a specific step in semiconductor architecture, standards, AI software or system integration. For contract manufacturing qualification in the processing-in-memory ai chips market, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For multi-year supply agreements in the processing-in-memory ai chips market, hardware buyers also need stable software tools, a defensible energy and performance profile and a supplier able to maintain the design through multiple production cycles. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Source - 17 December 2025 Announced
Mythic — Analog AI architecture financing. The 17 December 2025 company release documents a specific step in semiconductor architecture, standards, AI software or system integration. For component yield verification in the processing-in-memory ai chips market, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For deployment risk assessment in the processing-in-memory ai chips market, hardware buyers also need stable software tools, a defensible energy and performance profile and a supplier able to maintain the design through multiple production cycles. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Source - 18 November 2025 Announced
d-Matrix — Alchip 3D DRAM integration initiative. The 18 November 2025 company release documents a specific step in semiconductor architecture, standards, AI software or system integration. For regional distribution planning in the processing-in-memory ai chips market, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For technical product validation in the processing-in-memory ai chips market, hardware buyers also need stable software tools, a defensible energy and performance profile and a supplier able to maintain the design through multiple production cycles. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Source - 12 November 2025 Announced
d-Matrix — d-Matrix Series C financing. The 12 November 2025 company release documents a specific step in semiconductor architecture, standards, AI software or system integration. For factory-ramp planning in the processing-in-memory ai chips market, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For OEM sourcing negotiations in the processing-in-memory ai chips market, hardware buyers also need stable software tools, a defensible energy and performance profile and a supplier able to maintain the design through multiple production cycles. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Source - 2 July 2025 Published
IBM Research — Analog in-memory computing software stacks. The 2 July 2025 research publication documents a specific step in semiconductor architecture, standards, AI software or system integration. For product lifecycle qualification in the processing-in-memory ai chips market, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Source - 8 June 2025 Published
IBM Research — Analog/digital edge NPU proposal. The 8 June 2025 research publication documents a specific step in semiconductor architecture, standards, AI software or system integration. For near-term purchasing cycles in the processing-in-memory ai chips market, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For field reliability evaluation in the processing-in-memory ai chips market, hardware buyers also need stable software tools, a defensible energy and performance profile and a supplier able to maintain the design through multiple production cycles. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Source - 3 June 2025 Published
IBM Research — 64-core analog in-memory processor. The 3 June 2025 research talk documents a specific step in semiconductor architecture, standards, AI software or system integration. For device cost-down programs in the processing-in-memory ai chips market, the announced technology should not be conflated with certified annual market revenue: procurement depends on package specifications, integration, customer testing and commercial availability. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For contract manufacturing qualification in the processing-in-memory ai chips market, hardware buyers also need stable software tools, a defensible energy and performance profile and a supplier able to maintain the design through multiple production cycles. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. Source
REPORT SCOPE & SEGMENTATION
| Attribute | Details |
|---|---|
| Study Period | 2021–2036 |
| Historical Period | 2021–2025 |
| Base Year | 2026 |
| Base Year Market Size | USD 523.7 million |
| Estimated Year | 2027 |
| Estimated Year Market Size | USD 931.3 million |
| Forecast Year | 2036 |
| Forecast Market Size | USD 165,610.1 million |
| Forecast CAGR (2027–2036) | 77.8% |
| Currency / Measurement | USD million; revenue of included hardware |
| Market Boundary | Includes dedicated AI processing-in-memory chip products and memory devices with integrated compute capabilities. Excludes ordinary memory shipments without computing circuitry, stand-alone GPUs, and unrelated AI silicon whose processors have no memory-local execution engine; system boards and entire cloud racks are not added again as chip revenue. |
| By Type | DRAM-PIM · SRAM-PIM · Other Memory Types |
| By Application | Edge AI Systems · Data Center Accelerators · Automotive AI Processors · IoT Devices |
| By End User | Semiconductor Companies · Tech Startups · Research Institutions · Enterprise AI Adopters |
| By Architecture | Near-Memory Computing · In-Memory Processing · Compute-in-Memory |
| By Precision | Low-Precision (4-8 bit) · Medium-Precision (8-16 bit) · High-Precision (32+ bit) |
| By Region | 2026 regional market shares are estimates; the global revenue total is allocated once across the non-overlapping buying regions below. The processing-in-memory ai chips commercial scope remains distinct from adjacent hardware or platform offerings. North AmericaUnited States, Canada, Mexico Asia-PacificChina, Taiwan, South Korea, Japan EuropeGermany, France, United Kingdom, Netherlands Middle East & AfricaUnited Arab Emirates, Saudi Arabia, South Africa South AmericaBrazil, Chile, Argentina |
| Key Companies Profiled | Syntiant, Hangzhou Zhicun (Witmem) Technology, Shenzhen Reexen Technology, Mythic, Beijing Pingxin Technology, Graphcore, Axelera AI, AistarTek, Suzhou Yizhu Intelligent Technology, Beijing Houmo Technology, Samsung, SK hynix, d-Matrix, EnCharge AI |
| Customization Scope | For memory-local AI inference silicon, available detail includes region and customer-type splits, component specification coverage, supplier qualification criteria and country or state-level analysis within the defined market boundary. |
Frequently Asked Questions
How large is the processing-in-memory ai chips market?
The processing-in-memory ai chips market totals USD 523.7 million in 2026 and is projected to reach USD 165,610.1 million in 2036, equivalent to 77.8% CAGR during the 2027–2036 forecast period. For memory-local AI inference silicon, these values cover the report-defined semiconductor or accelerator card product category and should not be read as total AI capital expenditure. For memory-local AI inference silicon, the commercial market is influenced by qualified systems, application-specific silicon demand and availability of manufacturing and integration services.
Which technology type leads processing-in-memory ai chips?
DRAM-PIM has the largest estimated 2026 share at ~50% among the stated Type members. For memory-local AI inference silicon, its commercial positioning depends on the exact compute architecture and applications supported by vendors, rather than on company-wide semiconductor sales. Other type classes address distinct memory, latency, software or power constraints. For memory-local AI inference silicon, the share split is a scenario allocation across non-overlapping primary products; the published source does not disclose audited 2026 revenue for every segment.
What is the fastest growing type of processing-in-memory ai chips?
SRAM-PIM has the highest modeled type growth at ~82.4% CAGR, measured consistently against the modeled 2026 market breakdown. For memory-local AI inference silicon, the result reflects the technical advantages of the category and its anticipated procurement cycles, but also depends on manufacturing scale and mature development tools. For memory-local AI inference silicon, prototype demonstrations, IP agreements and design wins are not counted automatically as a completed shipment.
Which end-use application has the largest share?
Edge AI Systems is the leading application with an estimated ~38% of 2026 revenue. For memory-local AI inference silicon, buyers in this segment evaluate performance against device constraints and the cost of maintaining systems over several years. For memory-local AI inference silicon, application boundaries follow the stated primary customer use case, helping avoid counting the same hardware once as AI equipment and again as general-purpose data-center infrastructure.
Which region has the largest processing-in-memory ai chips demand?
North America leads at an estimated ~39% in 2026, ahead of Asia-Pacific at ~36% and Europe at ~17%. These indicative shares are allocated according to likely hardware purchasing and integration activity. For memory-local AI inference silicon, they do not claim audited national sales or equate corporate headquarters with the geographic location of an actual chip or PCIe-card shipment.
How do regional growth rates compare?
Asia-Pacific has the fastest modeled CAGR at ~80.3% during the 2026–2036 modeling horizon. For memory-local AI inference silicon, its prospects reflect available semiconductor and application ecosystems and the expected rate of customer qualification. For memory-local AI inference silicon, the regional models all reconcile with the common global forecast, but different deployment schedules, component pricing and supply constraints may produce actual outcomes that depart from these estimates.
What is included in the product definition?
For multi-year supply agreements in the processing-in-memory ai chips market, excludes ordinary memory shipments without computing circuitry, stand-alone GPUs, and unrelated AI silicon whose processors have no memory-local execution engine; system boards and entire cloud racks are not added again as chip revenue. This consideration continues to affect customer decisions across the 2026–2036 planning horizon. For memory-local AI inference silicon, the precise distinction matters because processor IP licenses, memory sold solely for storage, an integrated server system and a standalone PCIe card may represent different stages of the semiconductor value chain. For memory-local AI inference silicon, commercial comparisons must therefore distinguish the marketable item delivered to the customer before assigning sales volumes, pricing and competitive market position.
Who are important participants in processing-in-memory ai chips?
The profiled ecosystem includes Syntiant, Hangzhou Zhicun (Witmem) Technology, Shenzhen Reexen Technology and other relevant firms. For memory-local AI inference silicon, their roles differ between device manufacturing, accelerator architecture, software, chip intellectual property and systems integration. For memory-local AI inference silicon, a profiled company should be treated as a directly comparable supplier only where there is evidence of a product in the defined market. For memory-local AI inference silicon, acquired brands and adjacent service businesses should not be added again as independent hardware manufacturers.
What technical risks limit processing-in-memory ai chips adoption?
Manufacturing yield, device power, memory hierarchy and software qualification remain central commercialization risks for processing-in-memory ai chips. For memory-local AI inference silicon, chiplet architectures add die-to-die verification; processing-in-memory introduces accuracy and programming constraints; PCIe cards face slot, cooling and host-compatibility limits. For memory-local AI inference silicon, the severity differs by application, so customers evaluate representative end-to-end performance before selecting a device. Long support cycles are often as important as peak compute throughput.
What period and segments does the market cover?
For memory-local AI inference silicon, the study uses 2026 as the base, 2027 as the estimated year and 2036 as the forecast endpoint, with historical context for 2021–2025. Its Type categories are DRAM-PIM, SRAM-PIM, Other Memory Types; the primary Application categories are Edge AI Systems, Data Center Accelerators, Automotive AI Processors, IoT Devices. For memory-local AI inference silicon, regional comparisons divide global demand into five non-overlapping geographic groupings, while secondary classifications add engineering context without separately adding the same chip revenue.
Research Sources & Evidence Base
Get Sample Report PDF for Exclusive Insights
Report Sample Includes
- Table of Contents
- List of Tables & Figures
- Charts, Research Methodology, and more...
 Download Sample Report PDF