Key Statistics
Key Takeaways
- Model-based synthetic data is the leading type because generative models can reproduce complex statistical structure while separating development workflows from direct use of sensitive records.
- Autonomous vehicle training is the leading application in the report scope because simulation can generate rare or hazardous scenarios with labels derived directly from the virtual environment.
- North America is the leading commercialization region, supported by major cloud and AI platforms, autonomous-system developers and specialist synthetic-data vendors.
- Privacy engineering is a core demand mechanism. The UK ICO describes synthetic data as a form of randomisation that creates new data while maintaining statistical properties without retaining original data points.
- Quality and provenance are major constraints. NIST synthetic-content work and EU AI transparency requirements increase the need for evaluation, provenance, marking and detection controls.
Synthetic Data AI Market Overview
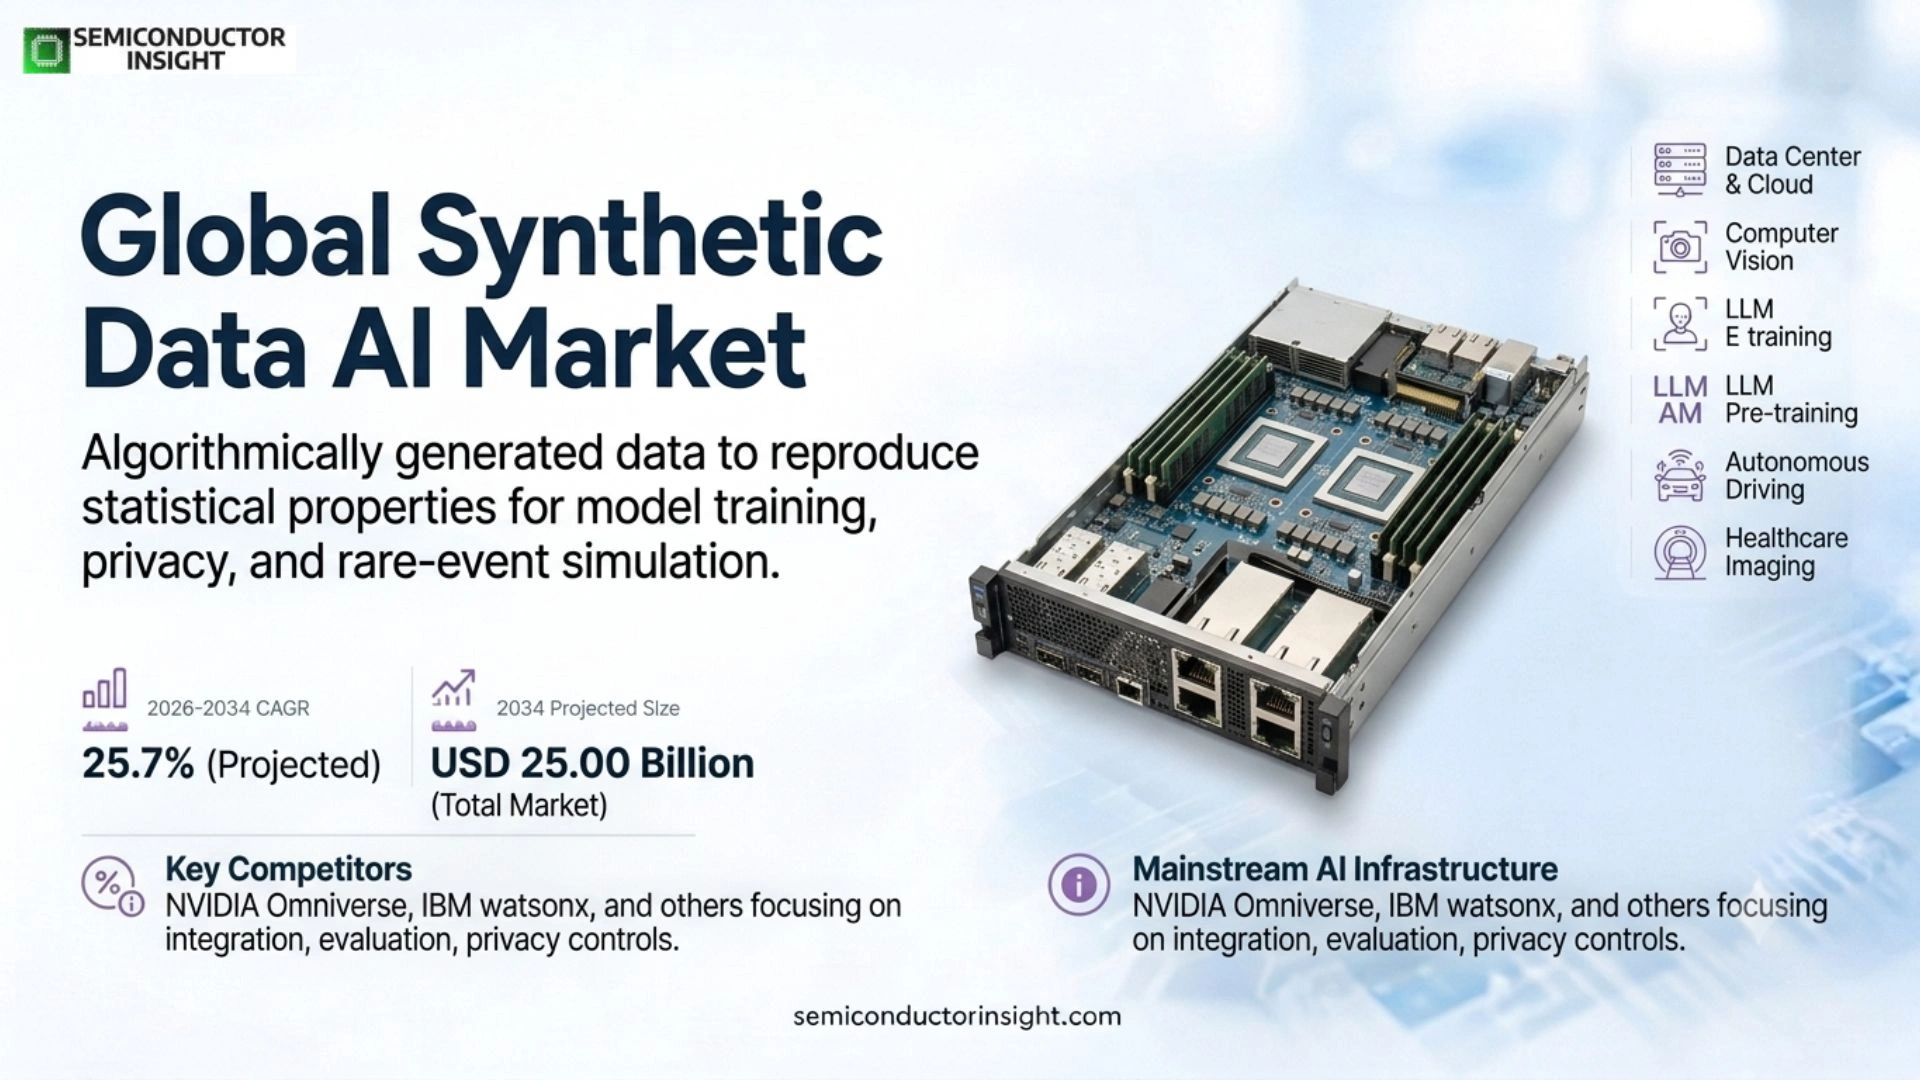
Synthetic Data AI market is valued at USD 3.20 billion in 2025 and is projected to reach USD 25.00 billion by 2034, representing a 25.7% CAGR during 2026–2034. The 2026 estimated market size is USD 4.02 billion. North America is the leading commercialization region, supported by major AI platforms, cloud infrastructure, enterprise adoption and specialized synthetic-data providers.
Base year: 2025 · Estimated year: 2026 · Forecast period: 2026–2034 · Historical data: 2021–2025 · Values in USD
Synthetic data is algorithmically generated information designed to reproduce useful properties of real data without simply copying source records. The UK Information Commissioner’s Office describes it as a type of randomisation in which algorithms create new data that maintain statistical properties while aiming not to include original data points. Commercial use cases include model training, testing, augmentation, privacy protection and rare-event simulation.
The market includes model-based and simulation-based generation across autonomous driving, computer vision, large-language-model pre-training and healthcare imaging, with additional segmentation by end user, generation methodology and deployment mode. A tabular privacy workflow in finance has very different quality and governance requirements from a physically based 3D simulation used to train autonomous perception.
Synthetic generation is becoming part of mainstream AI infrastructure. NVIDIA Omniverse Replicator provides a framework for custom synthetic 3D data pipelines, while IBM watsonx Synthetic Data Generator supports structured and unstructured datasets used in enterprise model development. Competition therefore centers on integration, evaluation, privacy controls and domain-specific quality as much as generation algorithms.
Segment Analysis: By Type
By type, the report segments the market into Model-based Synthetic Data and Simulation-based Synthetic Data. Model-based generation is the leading type because it can learn statistical or semantic patterns and create new structured or unstructured samples, while simulation methods are indispensable where physics, geometry and rare scenarios need explicit control.
| Type | Generation approach | Market position |
|---|---|---|
| Model-based Synthetic Data | Uses generative statistical or machine-learning models to learn distributions, correlations or semantic patterns and create new samples. Implementations can include GANs, diffusion models and foundation models. | Leading type. Broad applicability across tabular, text, image and enterprise data workflows supports privacy-preserving analytics, testing, training and augmentation. Differentiation depends on fidelity, privacy testing and controllability. |
| Simulation-based Synthetic Data | Uses rules, physics, 3D environments or digital representations to generate observations and labels. Developers control scenes, object behavior, sensors and event frequency. | Critical for autonomous vehicles, robotics and perception systems because rare or hazardous scenarios can be generated safely and repeatedly. NVIDIA Omniverse Replicator is a representative platform. |
Secondary segmentation
The report adds end user, generation methodology and deployment mode. Technology providers lead because they embed generation into broader AI platforms; GAN, diffusion and rule-based methods address different modalities and control needs; cloud-native deployment leads where elastic compute matters, while on-premises and hybrid options address sensitive data and residency requirements.
| Axis | Segments | Commercial implication |
|---|---|---|
| End User | Technology Providers · Financial Services · Healthcare Organizations | Technology platforms integrate generation into AI suites, while finance and healthcare emphasize privacy validation, governance and domain fidelity. |
| Generation Methodology | GAN-Driven Generation · Diffusion Model Generation · Rule-Based Simulation | Methods trade off realism, controllability, compute cost and data modality; no single approach is optimal for every dataset. |
| Deployment Mode | On-Premises Solutions · Cloud-Native Services · Hybrid Offerings | Cloud offers elastic scale, while on-premises and hybrid options address sensitive data, residency and controlled environments. |
Segment Analysis: By Application
By application, the report covers Autonomous Vehicle Training, Computer Vision for Retail, Large Language Model Pre-training and Healthcare Imaging. Autonomous-vehicle training leads because virtual environments can create rare, dangerous or statistically underrepresented scenarios with ground-truth labels that would be costly or unsafe to collect on public roads.
| Application | Demand characteristics |
|---|---|
| Autonomous Vehicle Training | Simulation can create weather, lighting, traffic, sensor and edge-case scenarios repeatedly with exact labels. Commercial value depends on physical realism, sensor modeling and integration into validation pipelines. |
| Computer Vision for Retail | Synthetic images can rebalance rare classes and create annotations automatically. The main constraint is domain gap: generated scenes must capture enough real-world variation for deployed models to perform reliably. |
| Large Language Model Pre-training | Synthetic text and task data can expand instruction, evaluation and domain-specific datasets when curated real data are limited. IBM supports unstructured synthetic datasets for tuning and evaluating foundation models. |
| Healthcare Imaging | Synthetic images and records can support model development where patient privacy and rare conditions limit real-world data access. Buyers need clinical fidelity and privacy validation rather than realism alone. |
Regional Analysis
North America is the leading commercialization region for Synthetic Data AI, supported by cloud platforms, AI infrastructure, autonomous-system development and enterprise adoption. Europe is shaped by privacy and AI regulation, Asia Pacific is expanding with digitalization and AI investment, and other regions remain earlier-stage markets.
How does regional demand differ across the Synthetic Data AI market?
Adoption follows AI maturity, compute access, data-governance pressure and the mix of regulated or simulation-heavy industries. North America has the broadest provider ecosystem. Europe turns privacy and responsible-AI requirements into demand for governed generation. Asia Pacific combines large digital markets with expanding AI investment. Emerging regions adopt where sensitive-data access or scarcity limits conventional model development.
| Region | Position | Growth outlook | Demand profile | Supplier selection |
|---|---|---|---|---|
| North America | Leading commercialization | Very high | Platform & enterprise led | Workflow integration, quality, governance and scale |
| Europe | Regulation-led growth | High | Privacy & responsible AI | Privacy assurance, data residency and auditability |
| Asia Pacific | Rapid expansion | Very high | Digitalization & AI investment | Localization, scale and domain performance |
| South America | Emerging | High from smaller base | Finance & healthcare | Cost, cloud access and local support |
| Middle East & Africa | Early-stage growth | High from smaller base | Government & digital transformation | Sovereignty, skills and compute access |
Competitive Landscape
The market combines hyperscale cloud and AI platforms with specialist synthetic-data vendors. The report profiles IBM Watson, Google Cloud Vertex AI, Microsoft Azure Machine Learning, AWS SageMaker Ground Truth, Hazy, Mostly AI, Tonic AI, Gretel.ai, Synthesis AI, DataRobot, Databricks and NVIDIA Omniverse. Competition centers on data modality, privacy controls, integration, evaluation and domain-specific generation quality.
Large platform vendors compete by embedding synthetic generation into broader model-development, data-engineering and cloud workflows. Their advantage is distribution: customers can generate data, train models and manage governance inside one environment, reducing integration cost.
Specialist vendors compete through deeper privacy, tabular-data and vertical workflows. They can focus on attack-based privacy testing, referential integrity, statistical fidelity or domain schemas, but must still pass enterprise security and integration reviews.
Simulation platforms form a distinct layer. Physically based 3D generation for autonomous systems requires different evaluation than tabular financial data, so the market cannot be judged with one universal quality metric.
Competitive tier structure
| Tier | Companies | Basis of competition |
|---|---|---|
| Platform leaders | IBM Watson; Google Cloud Vertex AI; Microsoft Azure Machine Learning; AWS SageMaker Ground Truth; NVIDIA Omniverse | Enterprise distribution, compute scale, AI workflow integration and security |
| Specialists | Hazy; Mostly AI; Tonic AI; Gretel.ai; Synthesis AI | Privacy-preserving generation, vertical focus, controllability and specialized evaluation |
| Data / AI platforms | DataRobot; Databricks | Integration with enterprise data science, model operations and governance |
Key companies profiled in the report scope
- IBM Watson
- Google Cloud Vertex AI
- Microsoft Azure Machine Learning
- AWS SageMaker Ground Truth
- Hazy
- Mostly AI
- Tonic AI
- Gretel.ai
- Synthesis AI
- DataRobot
- Databricks
- NVIDIA Omniverse
Synthetic Data Generation Infrastructure & Capacity Analysis
Synthetic-data capacity is software-defined rather than factory-defined. Practical constraints include compute availability, model throughput, simulator complexity, source-data governance, storage and evaluation. Cloud-native services can scale elastically, but cost per useful sample depends on data modality, quality thresholds and how much generated output fails validation.
Structured tabular generation can be relatively compute efficient, while image, video, 3D simulation and foundation-model generation can consume substantial GPU resources. Raw sample throughput is therefore a weak capacity metric if many samples fail fidelity, diversity, privacy or downstream performance checks. Useful-data yield is the software equivalent of manufacturing yield.
Infrastructure design also depends on sensitivity. Regulated organizations may prefer on-premises or hybrid deployment so source data remain within a controlled boundary, while simulation workloads rely on GPU and rendering infrastructure. The market spans cloud APIs, enterprise software, simulation platforms and governance tooling rather than one homogeneous capacity model.
Market Dynamics
Growth is driven by privacy constraints, data scarcity, model-development scale and simulation-heavy AI applications. The main restraints are data-quality risk, privacy leakage, evaluation complexity and compute cost. The market is moving from generating more data toward generating data whose utility, privacy and origin can be demonstrated.
MARKET DRIVERS
Drivers Impact Analysis*
| Factor | Forecast impact* | Geographic relevance | Impact timeline |
|---|---|---|---|
| Privacy-preserving model development | High | Europe, North America, regulated industries | Short to long term |
| Autonomous systems & simulation | High | North America, Asia Pacific, Europe | Medium to long term |
| Foundation-model tuning & evaluation | High | Global | Short to medium term |
| Cloud integration & elastic compute | Medium to high | Global cloud markets | Short term |
*Directional analytical rating; not a measured contribution to the headline CAGR.
Privacy constraints turn data access into a product problem
Organizations often possess useful data but cannot expose it freely to every developer or test environment. ICO guidance identifies synthetic data as a randomisation technique that can preserve statistical properties without retaining original data points, creating a commercial use case for platforms that can generate useful alternatives and measure privacy risk.
Autonomous systems need rare scenarios
Road driving, robotics and machine vision contain low-frequency but safety-critical events. Simulation lets developers increase those scenarios intentionally and obtain labels from the environment, making simulation-based generation a core market segment.
Foundation-model workflows need domain-specific tasks
Enterprise LLM programs need instruction, question-answer, tool-use and evaluation datasets tailored to internal domains. IBM supports unstructured synthetic generation for foundation-model tuning and evaluation, expanding the category beyond privacy-oriented tabular data.
Cloud integration reduces adoption barriers
Synthetic generation often requires bursty compute. Cloud-native services let users scale jobs and connect to existing data pipelines, shifting procurement from a stand-alone tool toward a capability inside a broader AI platform.
MARKET RESTRAINTS
Restraints Impact Analysis*
| Factor | Forecast impact* | Geographic relevance | Impact timeline |
|---|---|---|---|
| Synthetic-to-real domain gap | High | All model-development markets | Persistent |
| Privacy leakage & memorization risk | High | Regulated sectors | Persistent |
| Evaluation & standardization gaps | High | Global | Medium term |
| Compute & storage cost | Medium | Vision, video and LLM workloads | Short to medium term |
*Directional analytical rating; not a measured contribution to the headline CAGR.
Synthetic data can preserve the wrong patterns
A generated dataset can look realistic yet omit rare causal relationships, under-represent edge cases or reproduce bias from source data. Buyers therefore need downstream utility validation, not only visual similarity or distribution-level statistics.
Privacy is not automatic
Generating new samples does not guarantee that sensitive information cannot be inferred. Robust deployments may require membership-inference, attribute-inference or other attack-based tests, especially in healthcare and finance.
Provenance requirements are expanding
NIST focuses on provenance, labeling, watermarking and detection for synthetic content, while Article 50 of the EU AI Act creates transparency obligations for certain generated outputs. This adds engineering requirements beyond the generator itself.
High-fidelity generation can be compute intensive
Photorealistic simulation, video and foundation-model generation consume GPU resources and storage. If many samples are filtered out during quality checks, cost per usable sample rises quickly.
MARKET OPPORTUNITIES
Make evaluation a first-class product layer
Platforms that generate and score data in one workflow can reduce enterprise adoption risk. Utility, privacy, diversity and downstream performance tests can turn synthetic data into a governed production input rather than an experimental dataset.
Build domain-specific generators for regulated industries
Healthcare, finance and government users need schemas, constraints, privacy controls and deployment options that generic generators do not provide. Domain-specific validation can become a durable moat.
Expand synthetic data for agentic AI and tool use
Foundation-model applications increasingly need examples for tool calling, text-to-SQL, retrieval and multi-step workflows. High-quality synthetic tasks can improve coverage where manually authored examples are expensive or real logs are sparse.
Combine simulation with real data for digital twins
Industrial, robotic and autonomous systems can blend real sensor logs with simulated scenarios to cover rare or dangerous operating states, creating opportunities for integrated scene generation and validation platforms.
Synthetic Data Value Chain Analysis
Source preparation determines the ceiling
Synthetic generation starts with production data, schemas, business rules, simulators, seed examples or domain documents. Poor source coverage limits the generator regardless of model sophistication, so connectors, profiling and constraints are important product capabilities.
Generation algorithms are becoming more accessible
GANs, diffusion models and foundation models are increasingly available through cloud APIs and open frameworks. Durable differentiation therefore shifts toward controllability, schema support, privacy mechanisms, simulator assets and repeatable workflows.
Evaluation is the critical middle layer
A dataset has limited enterprise value if users cannot show that it is useful, private, diverse and traceable. Statistical comparisons, task-based utility tests, privacy attacks and provenance controls increasingly determine whether data can enter production.
Downstream model performance is the ultimate value test
Customers buy synthetic data to improve training, testing, validation or software quality. Providers that measure impact on the downstream task can defend value more effectively than vendors that sell dataset volume alone.
Recent Developments in the Synthetic Data AI Market
IBM adds PDF-backed knowledge generation
IBM added PDF reference documents to its knowledge data-builder pipeline and expanded unstructured synthetic-data workflows for foundation-model applications.
NIST publishes synthetic-content transparency approaches
NIST AI 100-4 reviews provenance, watermarking, labeling and detection approaches, reinforcing the importance of traceability and evaluation tooling.
EU AI Act Article 50 establishes transparency obligations
The regulation requires providers of certain systems generating synthetic audio, image, video or text to make outputs machine-readably marked and detectable, subject to stated exceptions.
NVIDIA Omniverse Replicator supports synthetic 3D pipelines
Replicator provides workflows for building synthetic-data generation and annotation pipelines used in autonomous systems, robotics and video analytics.
REPORT SCOPE & SEGMENTATION
| Attribute | Details |
|---|---|
| Study Period | 2021–2034 |
| Base Year | 2025 |
| Estimated Year | 2026 |
| Forecast Period | 2026–2034 |
| Historical Period | 2021–2025 |
| Market Size 2025 | USD 3.20 billion |
| Market Size 2034 | USD 25.00 billion |
| Growth Rate | CAGR of 25.7% from 2026–2034 |
| Unit | Value (USD Million/Billion) |
| Segmentation | By Type, By Application, By End User, By Generation Methodology, By Deployment Mode |
| By Type | Model-based Synthetic Data · Simulation-based Synthetic Data |
| By Application | Autonomous Vehicle Training · Computer Vision for Retail · Large Language Model Pre-training · Healthcare Imaging |
| By End User | Technology Providers · Financial Services · Healthcare Organizations |
| By Generation Methodology | GAN-Driven Generation · Diffusion Model Generation · Rule-Based Simulation |
| By Deployment Mode | On-Premises Solutions · Cloud-Native Services · Hybrid Offerings |
| By Region | Each region analysed by Type, Application and major commercial marketsNorth AmericaUnited States, CanadaEuropeUnited Kingdom, Germany, France and other European marketsAsia PacificChina, Japan, India, South Korea, Southeast AsiaSouth AmericaBrazil, Argentina and other South American marketsMiddle East & AfricaUAE, Saudi Arabia, South Africa and other MEA markets |
| Key Companies Profiled | IBM Watson · Google Cloud Vertex AI · Microsoft Azure Machine Learning · AWS SageMaker Ground Truth · Hazy · Mostly AI · Tonic AI · Gretel.ai · Synthesis AI · DataRobot · Databricks · NVIDIA Omniverse |
| Customization Scope | Free report customization equivalent to up to four analyst working days with purchase. Addition or alteration to country, regional and segment scope. |
Frequently Asked Questions
What is the current size of the Synthetic Data AI market?
The market is valued at USD 3.20 billion in 2025 and is projected to reach USD 25.00 billion by 2034, implying a 25.7% CAGR during 2026–2034. The 2026 estimated market size is USD 4.02 billion. The source page already provides the requested 2025 and 2034 endpoint values.
Which type leads the market?
Model-based synthetic data is the leading type because generative models can reproduce complex statistical or semantic patterns across structured and unstructured data. Simulation-based data remains critical for autonomous systems where physics and rare events need explicit control.
Which application leads the market?
Autonomous vehicle training is the leading application in the report scope. Simulation can generate dangerous, rare or underrepresented driving situations repeatedly and with automatic labels, reducing dependence on road collection for every scenario.
Which region leads in 2025?
North America is treated as the leading commercialization region because it combines major cloud and AI platforms, autonomous-system developers, enterprise buyers and specialist synthetic-data vendors.
What is the estimated market size in 2026?
The 2026 market size is estimated at USD 4.02 billion and sits on the constant-growth path between the retained USD 3.20 billion 2025 base and USD 25.00 billion 2034 forecast endpoint.
What are the main growth drivers?
The main drivers are privacy-preserving model development, data scarcity, autonomous-system simulation, foundation-model tuning and evaluation, and cloud integration that lowers infrastructure barriers.
What are the main restraints?
The main restraints are synthetic-to-real domain gap, privacy leakage or memorization risk, lack of universal quality standards, expanding provenance requirements and compute cost for high-fidelity generation.
How is regulation affecting the market?
Privacy rules motivate reduced use of sensitive source records, while the EU AI Act creates transparency requirements for certain synthetic content and NIST documents technical approaches to provenance, marking and detection.
What is the most important opportunity through 2034?
The strongest opportunity is to combine generation with automated evaluation, privacy testing and domain-specific controls, because enterprise buyers increasingly need evidence of utility, privacy and provenance.
What segmentation does the report cover?
The report covers model-based and simulation-based types; autonomous vehicles, retail vision, LLM and healthcare applications; end-user, generation-method and deployment-mode segments; and five global regions.
Research Sources & Evidence Base
View primary and authoritative evidence used in this overview
- UK Information Commissioner’s Office. How do we ensure anonymisation is effective? – Official guidance defining synthetic data within randomisation and anonymisation.
- National Institute of Standards and Technology. Reducing Risks Posed by Synthetic Content – November 2024 evidence on provenance, watermarking, labeling and detection.
- European Union / EUR-Lex. Regulation (EU) 2024/1689 – Article 50 – Official legal text on transparency obligations for certain synthetic content.
- NVIDIA. Omniverse Replicator documentation – Technical documentation for custom synthetic 3D data generation pipelines.
- IBM. Generating synthetic data with watsonx – Product documentation for structured and unstructured synthetic-data workflows.
- IBM. What’s new in Synthetic Data Generator – 2025 evidence on PDF-backed knowledge generation and expanded workflows.
Get Sample Report PDF for Exclusive Insights
Report Sample Includes
- Table of Contents
- List of Tables & Figures
- Charts, Research Methodology, and more...
 Download Sample Report PDF